Inference made for the multi-model organization seeking maximum quality and control.
Get frontier-grade open inference for your agentic workloads. Scale as traffic grows. Deploy the latest open models without rewriting your stack.
Superior Quality
Every model passes a published quality bar before it serves, and what you train is what you serve.
Superior quality
Most providers run a general-purpose stack and tune at the edges. Our proprietary engine optimizes every layer, from GPU memory layout to runtime. The result: up to 4x higher throughput than vLLM and industry-leading latency, without sacrificing model quality. Every model is rigorously tested.
Build, not wrapped
Custom attention kernels, speculative decoding and advanced caching work together in one stack, and FireOptimizer tunes the serving setup to each workload.
Tested before it serves
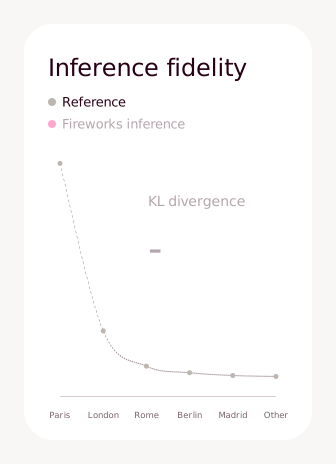
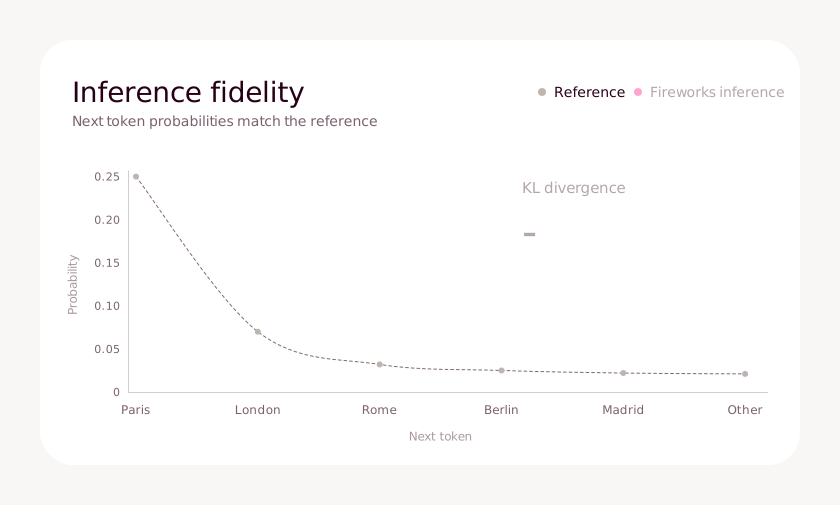
Each model is held to published limits: KL divergence below ~0.007 and token rejection below ~3% against an unquantized reference. It’s also run side by side with the lab’s official API. Fast and Standard run the same weights and pass the same evals.
Quantized for quality
KV caching and routing are built for multi-turn agents and long context windows. Time to first token and output accuracy hold steady as conversations grow, instead of degrading.
What you train is what you serve
Training and serving share one stack, so your post-trained checkpoint behaves the same in production. No weight exports, no new platform, no revalidation.
Cost Efficiency
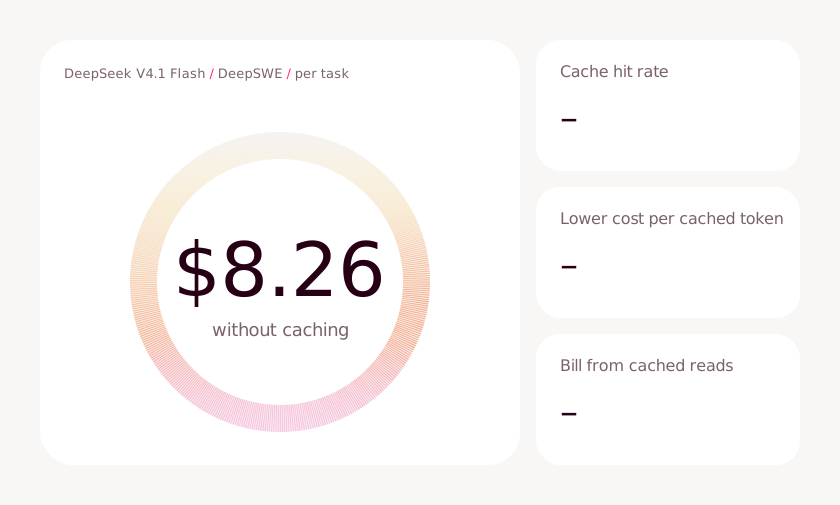
Built for cost per finished task. Long agent sessions hold cache hit rates up to 99.6%, so repeated context is billed at half price or less.
Cost efficiency
The price per token is only part of what you pay. What a finished task costs also depends on how much context gets reused, which model handles each turn, and how you run each job. We built for all of it: long agent sessions stay cached, each turn goes to the model that fits it, and every job runs the plan and performance options it requires.
Built for long-agent sessions
KV caching and routing are designed for multi-turn agents and long context windows. Time to first token and output accuracy hold as conversations grow.
High cache hit rate
Session affinity keeps each agent on the same server, where its context is already cached, so long runs reach cache hit rates up to 99.6%. Cached input is billed at half price or less, and writing to the cache is free.
Right task, right model
Fireworks offers intelligent routing models. Route amongst open models or open and closed models. Fireworks routing is both cache and task difficulty aware to optimize for both accuracy and cost.
Pay for what the job needs
Choose Batch for large async jobs, at 50% off. Choose Fast for interactive apps that need 100+ TPS. Choose Priority to keep requests flowing at peak traffic. Choose Reserved Throughput for guaranteed capacity.
Scale & Sovereignty
One endpoint on a global GPU fleet across 30+ regions, in our cloud or yours. Keep your data where your policies require.
Scale and Sovereignty
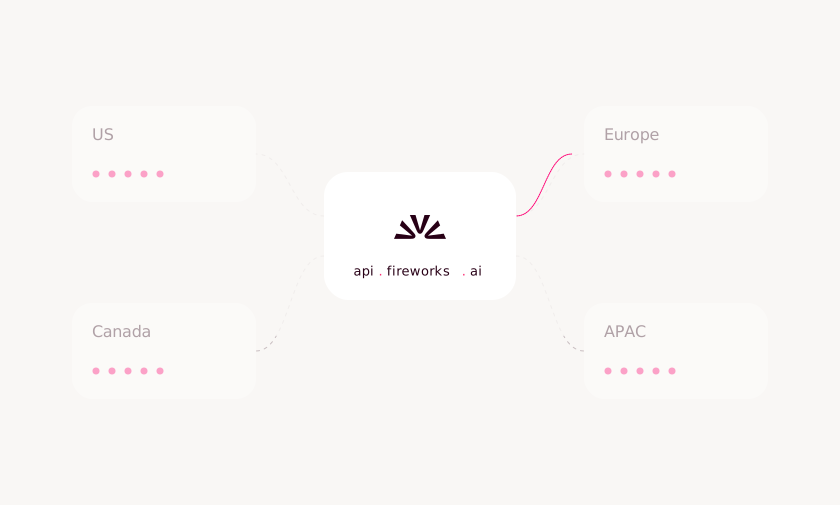
Fireworks runs on a global network of GPU fleets with the latest hardware across 30+ regions and dozens of providers. One deployment draws on all of it through a single endpoint, in our cloud or yours, and your data stays where your policies require.
Every stage scales on its own
Prefill and decode need different hardware, so we run them in separate pools that scale independently. That cuts latency without leaving GPUs idle. Frontier MoE models run across many machines, so trillion-parameter models reach production speed.
One endpoint, 30+ regions
One deployment draws on GPUs across 30+ regions, with automatic balancing and failover. Multi-region deployments reached 99.99%+ request success.
In our cloud or yours
Bring-Your-Own-Cloud (BYOC) runs the Fireworks stack on your Kubernetes clusters, in your cloud or data center, and we operate it. Move from serverless to dedicated, reserved or BYOC without changing your API calls.
Your data, your rules
Zero data retention by default. US-only Serverless and account-level data residency. SOC 2 Type II, ISO 27001, 27701 and 42001, and HIPAA with a BAA. For Azure customers, Fireworks is a first-party provider in Microsoft Foundry.