For enterprise
Build a durable competitive advantage.
Run, orchestrate, and train open models to launch faster, scale adoption, and control cost without compromising quality. Keep control of your data, models, and deployments.
Run, orchestrate, and train open models to launch faster, scale adoption, and control cost without compromising quality. Keep control of your data, models, and deployments.




Bring AI to more products, teams, and customers with the performance they expect and economics you control. Turn proprietary expertise into models that improve with your business.
Your traces, data, and expert judgment are the one input a general model can’t copy. Train open models on them, feed production results into every next run, and keep the weights. Each new open base model broadens your opportunity.
New open models arrive on Fireworks on launch day, behind OpenAI- and Anthropic-compatible APIs. Your evals decide what reaches production. Pin a model on a dedicated deployment, and change them on your schedule.
Expand access while selecting models against explicit quality and latency requirements. Keep premium models for the work that needs them and move the rest to open models. Let your teams leverage open models in the tools they already use with Fireworks Nexus.
Run with enterprise security controls, defined retention policies, and SLA-backed deployment options. ZDR by default, SOC 2 Type II, HIPAA, and ISO 27001 certified. Reserved Throughput and dedicated deployments carry 99.9% uptime terms.
Each model is custom deployed and benchmarked for optimized cost, speed, and quality. Which will you try first?
SOC 2 Type II, and ISO 27001, 27701, and 42001, with the controls your security, platform, and finance teams require.
Feature
Details
Zero data retention
Fireworks keeps no prompts or generations for open models by default. Enterprise admins can turn on an account-wide policy that blocks every feature that stores content.
Data residency
Pin your account’s inference to a region, starting with US-only endpoints. Requests outside the region don’t run. Need another region? Talk to us.
IP protection
Your training data and evals are never shared. Reward functions and rollout servers can run entirely in your environment, so the logic behind your model’s behavior is never shared.
Your storage, your keys
Keep datasets and checkpoints in your own GCS, S3, or Azure bucket, encrypted with your own KMS key. Dedicated workloads run in logically isolated environments.
Feature
Details
Reserved Throughput
Guaranteed throughput, backed by an SLA. Usage above your reservation bills at standard Serverless rates, with no penalty.
Multi-region deployments
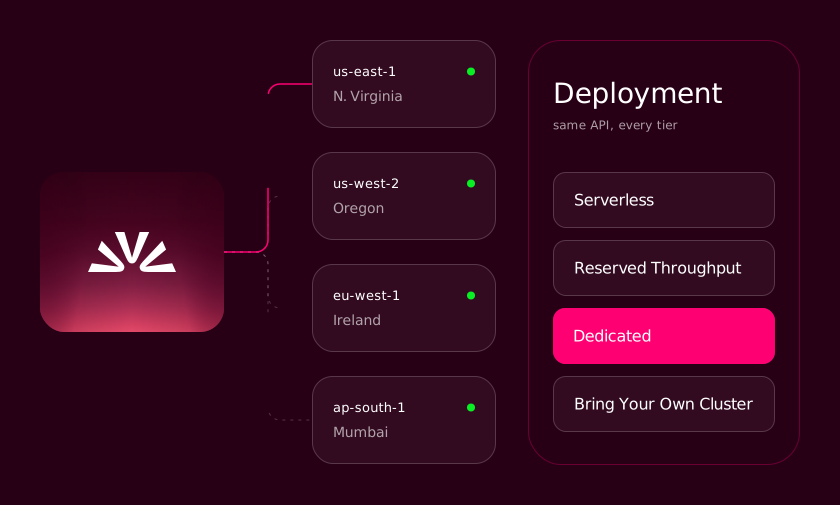
Dedicated deployments carry 99.9% uptime terms and can span 30+ regions across many clouds, all behind one endpoint.
Fireworks Sovereign
Run Fireworks-managed inference on GPUs in your own cloud account or data center. You own the environment, and Fireworks operates the serving stack.
Buy through Azure
Fireworks is a first-party inference provider in Microsoft Foundry. Usage bills through Azure and counts toward your Microsoft Azure Consumption Commitment.
Feature
Details
Custom SSO and SCIM
Sign in through your SAML 2.0 or OIDC identity provider and enforce SSO for every user. Sync users and groups from Okta, Microsoft Entra ID, or Google Workspace.
Model access policy
Approve the models your account can use, and for what: Serverless, Fast, dedicated deployments, or training.
Audit and access logs
Every read, write, and delete on your stored data is logged with account context. Filter by user, API key, or resource from the CLI or API.
Cost attribution
Tag each request by team, project, and environment with one header. Break down usage and cost by model, user, or API key for chargeback.
Reserve Throughput, dedicate deployments, or deploy on your own cloud as workloads mature. Deployments reach 30+ global regions behind a single endpoint.
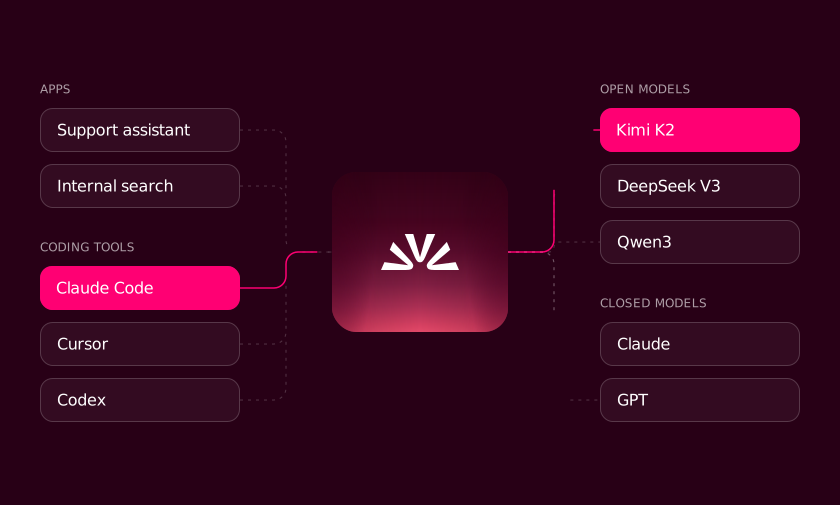
Send each workload to the model that meets its quality, latency, and cost requirements. Give your departments Nexus to intelligently orchestrate models to optimize cost and quality for every task. Nexus integrates with leading AI tools, including Claude Code, ChatGPT, Codex, Cursor, and more.
Turn proprietary data and expert judgment into a model your competitors can’t rent. Fireworks is one of the few organizations to run reinforcement learning across more than 10,000 GPUs. Datasets, checkpoints, and reward functions can stay in your cloud, and the weights are yours.
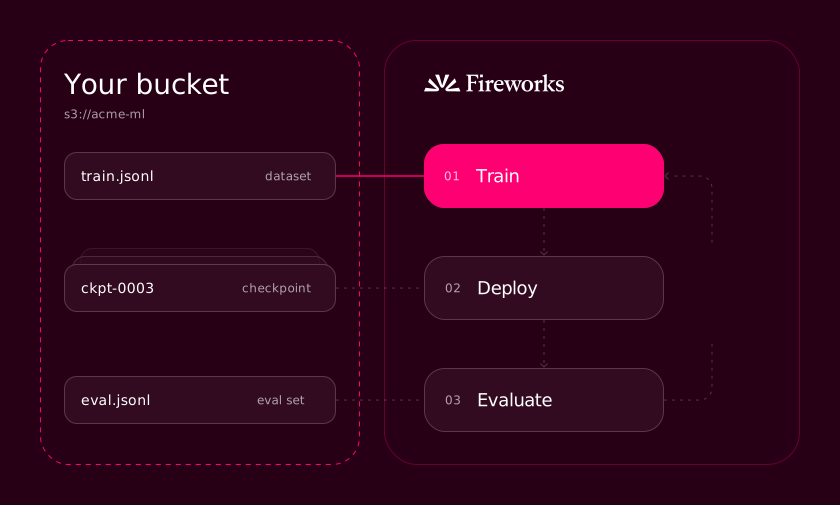
Embed leading ML researchers and forward-deployed engineers with your team to meet your quality targets and scale to production faster. Together, we define evaluations, design training strategies, and turn production feedback into measurable improvements with models, evals, and training recipes your team can leverage.
Put coding agents in every engineer’s hands, on models you govern.
Keep assistants fast for every user, at any scale. Notion cut latency from about 2s to 350ms for 100M+ users.
Run long agent loops on open models, and keep closed models for tasks where your evals favor them.
Serve semantic search and recommendations at enterprise volume, with US-only endpoints when residency rules apply.
Run vision, speech-to-text, image generation, and embeddings on one API, under the same retention and access policies.
Ground answers in your knowledge bases without giving up control of them. Deploy embedding and reranking models.
“Evaluating new models against our benchmarks usually requires trade-offs between performance, cost and scale, but Kimi K3 on Fireworks delivered across the board. The performance is top-tier, the serverless scaling is seamless, and the Zero Data Retention assurance gives us full confidence at scale.”
Fireworks is SOC 2 Type II and HIPAA compliant, signs BAAs, and holds ISO 27001, 27701, and 42001 certifications. For more information, you can find audit reports and certificates in the Trust Center.
Open-model inference runs with zero data retention by default, but a few features store content by design, such as the Responses API, batch jobs, and training. Enterprise admins can block all of them with one account-wide policy. Neither your inference data nor your training data is ever used to train Fireworks-owned or shared models.
Yes. Data residency restricts your account’s inference to one region, with US-only Serverless endpoints and US deployment regions available today. If you need a different region, talk to our team.
Yes, through Fireworks Sovereign, now in private preview for Enterprise customers. Fireworks operates the serving stack on GPUs in your cloud account or data center, and you keep ownership of the environment and its networking.
Reserved Throughput includes a throughput SLA, and both Reserved Throughput and dedicated deployments carry 99.9% uptime terms in our standard order form. Pay-as-you-go Serverless doesn’t carry an SLA.
Usage above your reservation bills at standard Serverless rates, never a penalty rate. Reserved Throughput adds to your adaptive rate limits. For training and fine-tuned models, we offer customized inference.
Yes. Fireworks is a first-party inference provider in Microsoft Foundry, so usage bills through Azure and counts toward your Microsoft Azure Consumption Commitment.
We give at least two weeks’ notice before removing a model from Serverless, longer for popular models, along with a recommended replacement. For a version that never changes, run it on a dedicated deployment, where updates happen only when you make them.
You do. The weights, evals, and training recipe belong to your company, and your traces stay with you instead of with a model lab. LoRA adapters export in standard Hugging Face PEFT format, and reward functions can stay in your environment.
Bring your SAML 2.0 or OIDC identity provider, enforce SSO, and sync users and groups with SCIM. Model access policy sets which models your account can use for Serverless, Fast, deployments, and training, and audit logs record who did what.
Yes. Add the Fireworks-Annotations header to tag requests by team, project, and environment, then pull usage and cost by model, user, or API key from the billing API.
Yes. Fireworks APIs are OpenAI- and Anthropic-compatible, so most teams point their existing gateway at Fireworks and run evals side by side. Keep closed models where they win, and move the rest when your evals say it’s ready.
Bring your requirements and your hardest workload. An expert will map the path from first deployment to a model you own.