Build your product’s edge into the models behind it. Run the latest open models, orchestrate for quality and cost, and train on what makes your company unique. All on one platform.


Start building with serverless inference. Scale with the performance, control, and economics to keep growing.
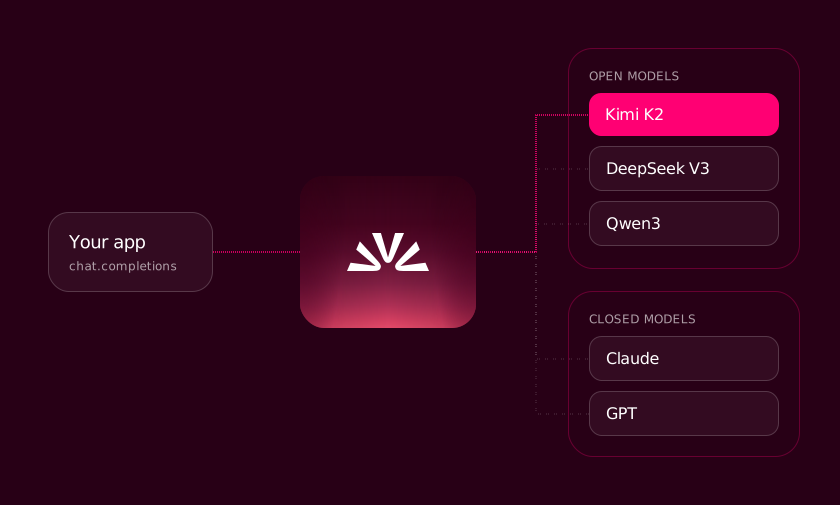
Access new open models on day zero through OpenAI- and Anthropic-compatible APIs. Update your endpoint, run your evals, and bring new capabilities into production on your schedule.
Make every inference dollar go further. Caching is enabled by default, with 80%+ savings on cached tokens for select models. Route to premium models where they add value, and optimize cost per completed task as usage grows.
Launch with pay-per-token pricing and no commitment. Give critical requests Priority treatment under load, then reserve throughput with an SLA as demand becomes predictable.
Turn your traces, evals, and customer feedback into capabilities unique to your product. Train open models, deploy checkpoints in one click, and keep the weights. Own what you build and control how it evolves.
Each model is custom deployed and benchmarked for optimized cost, speed, and quality. Which will you try first?


For Juicebox, slow talent searches mean lost customers. Hear how Fireworks helped its agents move faster while cutting annual inference costs by $3.2M.
Optimize your intelligence across your apps and people, giving every task the model it needs. Orchestrate through the Fireworks platform inside your apps and systems, or through Nexus in the tools your team already uses, like Claude Code, ChatGPT, Codex, and Cursor.
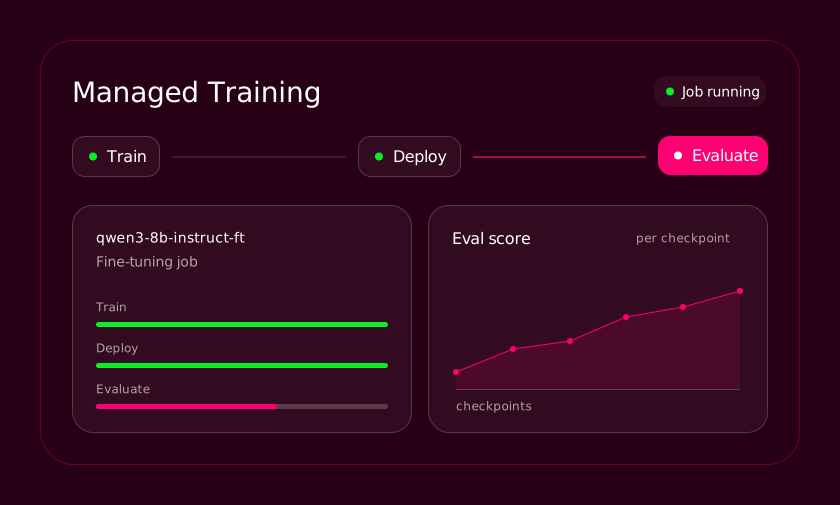
Start with Managed Training. Bring your data or evals, choose SFT, DPO, or RFT, and launch from the UI or API. Fireworks runs the training loop, with training and inference kept aligned, so the model you train is the model you serve. Deploy a checkpoint in one click. When you want full control, write your own loop with the Training API.
Fireworks Lab embeds ML researchers and forward-deployed engineers with your team. Together, you find the workloads worth training, build evals with your experts, and set targets for quality, cost, and latency before training begins. You keep the model, the evals, the data pipelines, and the recipes.
From experimentation to production, Fireworks provides the platform to build your generative AI capabilities: optimized and at scale.
Power completions, edits, and coding agents. Cursor trains and serves Composer on Fireworks at 6–10x lower inference cost.
Keep responses fast in every conversation. Heidi Health’s clinical scribe runs on fine-tuned open models with 3.5x lower latency.
Run reliable tool calls across long agent loops. Genspark’s research agent made 33% more tool calls than a leading closed model, at 50% lower cost.
Answer queries at scale, even when traffic spikes. Sentient served 5.6M+ queries in a week with zero degradation.
Build with vision, speech-to-text, image generation, and embeddings on one API.
Ground answers in your own data. Cresta runs real-time knowledge assist on thousands of LoRA adapters at 6x lower cost.
No. Serverless is pay-per-token with no commitment and no minimum. Add a payment method and credits, then call any serverless model through the OpenAI- or Anthropic-compatible API. The usage object in each response shows exactly what you were billed.
Yes. Our APIs are compatible with both. Most teams update the endpoint URL and API key, then run their evals side by side.
Every model is validated against the provider’s official API and reference before it serves traffic. Fast and Standard run the same weights and pass the same evals.
Mark critical requests as Priority, and they’re the last shed under load. For guaranteed capacity, Reserved Throughput includes a throughput SLA, and usage above your commitment bills at Serverless rates. Planning a launch? Talk to us about headroom ahead of time.
Limits are adaptive and measured in tokens per minute across three metrics: total prompt tokens, uncached prompt tokens, and generated tokens. Ceilings depend on model size and your spend tier.
Caching is automatic, with no setup and no write fee. Cached input tokens bill at a discount: the default is 50% off input, with deeper discounts on select models.
Standard is the default for most traffic. Priority costs more and is prioritized on the platform during peaks. Fast runs at 100+ tokens per second for latency-sensitive work. Batch costs 50% less on input and output for jobs that don’t need an immediate answer.
At least two weeks, and longer for popular models. Deprecations are announced by email and in the changelog, along with a recommended model to migrate to. If you need a model version that never changes, run it on a dedicated deployment, where you control updates.
No. Managed Training runs the loop for you: bring your data or evals and pick a method. If you want hands-on help, Fireworks Lab embeds researchers with your team from evaluation through production.
Yes. You keep the model, your evals, and your training recipe. LoRA adapters download in standard Hugging Face PEFT format.
Not by default. Open models run with zero data retention. Fireworks is SOC 2 Type II and HIPAA compliant, and we sign BAAs.
Yes. Fireworks bills against prepaid credits, and you can set a monthly spend limit on your account. Auto Reload keeps production running once your credits run low.
Instantly run popular and specialized models.