Fireworks Sovereign
Fireworks on your infrastructure.
Managed by Fireworks, governed by you, with 20 to 50% more tokens from the GPUs you own.
Managed by Fireworks, governed by you, with 20 to 50% more tokens from the GPUs you own.
More tokens per dollar of GPU hardware
From open model release to serving in your cluster
GPUs already managed in customer environments
Fireworks operates the inference on GPUs you control, including upgrades, performance optimization, and incident response. Your team retains ownership of the architecture and policies.
with upgrades, tuning, and incident response included.
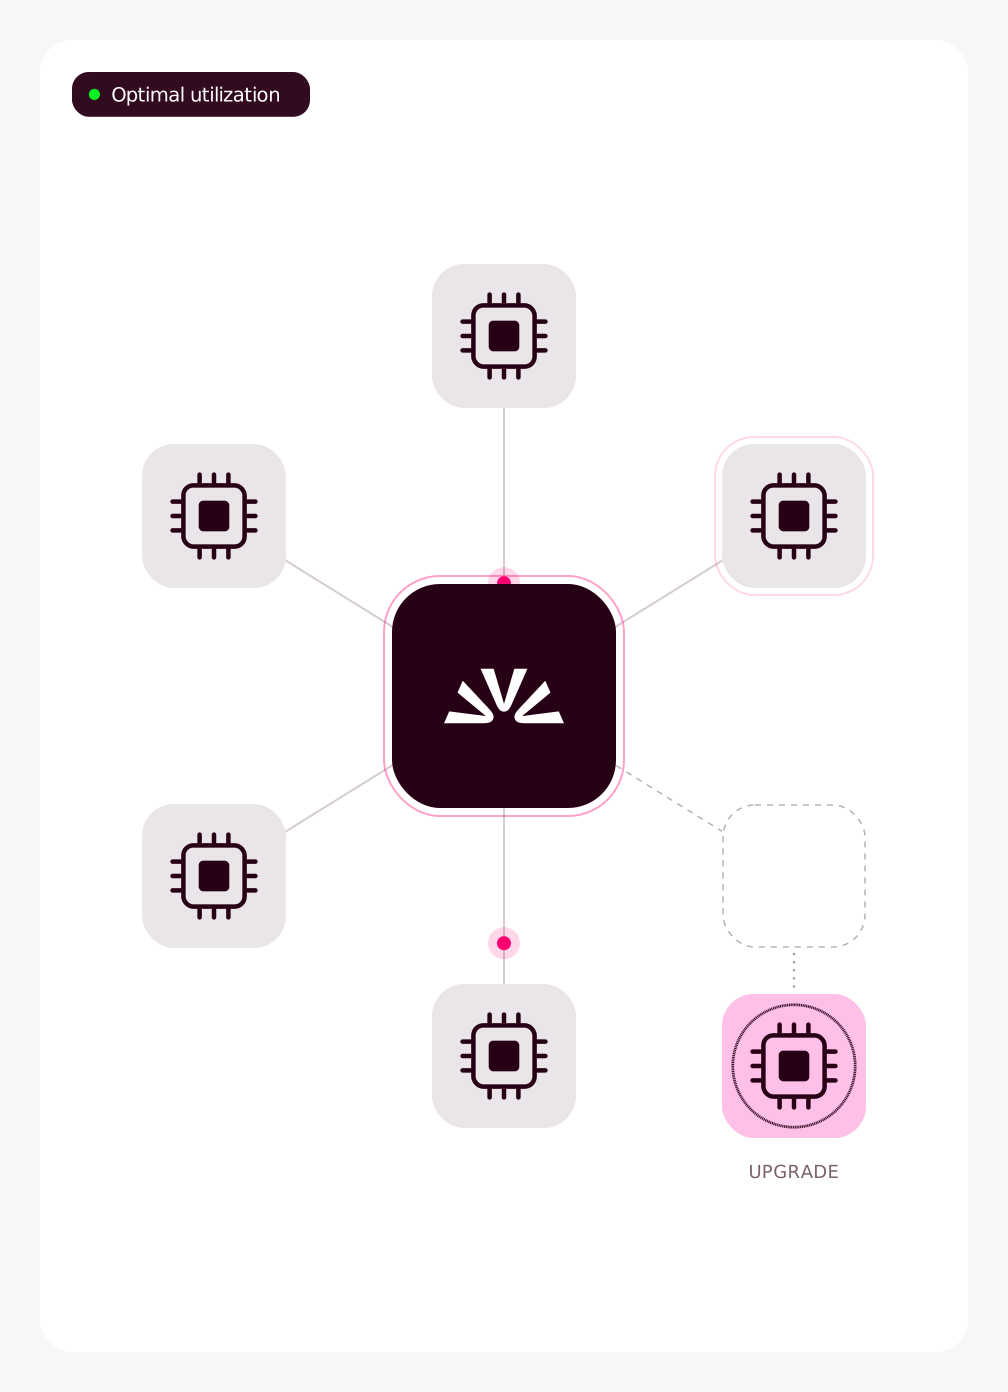
Fireworks qualifies your cluster, deploys your models, and is responsible for upgrades, monitoring, and incident response. Your platform team retains ownership of the architecture.
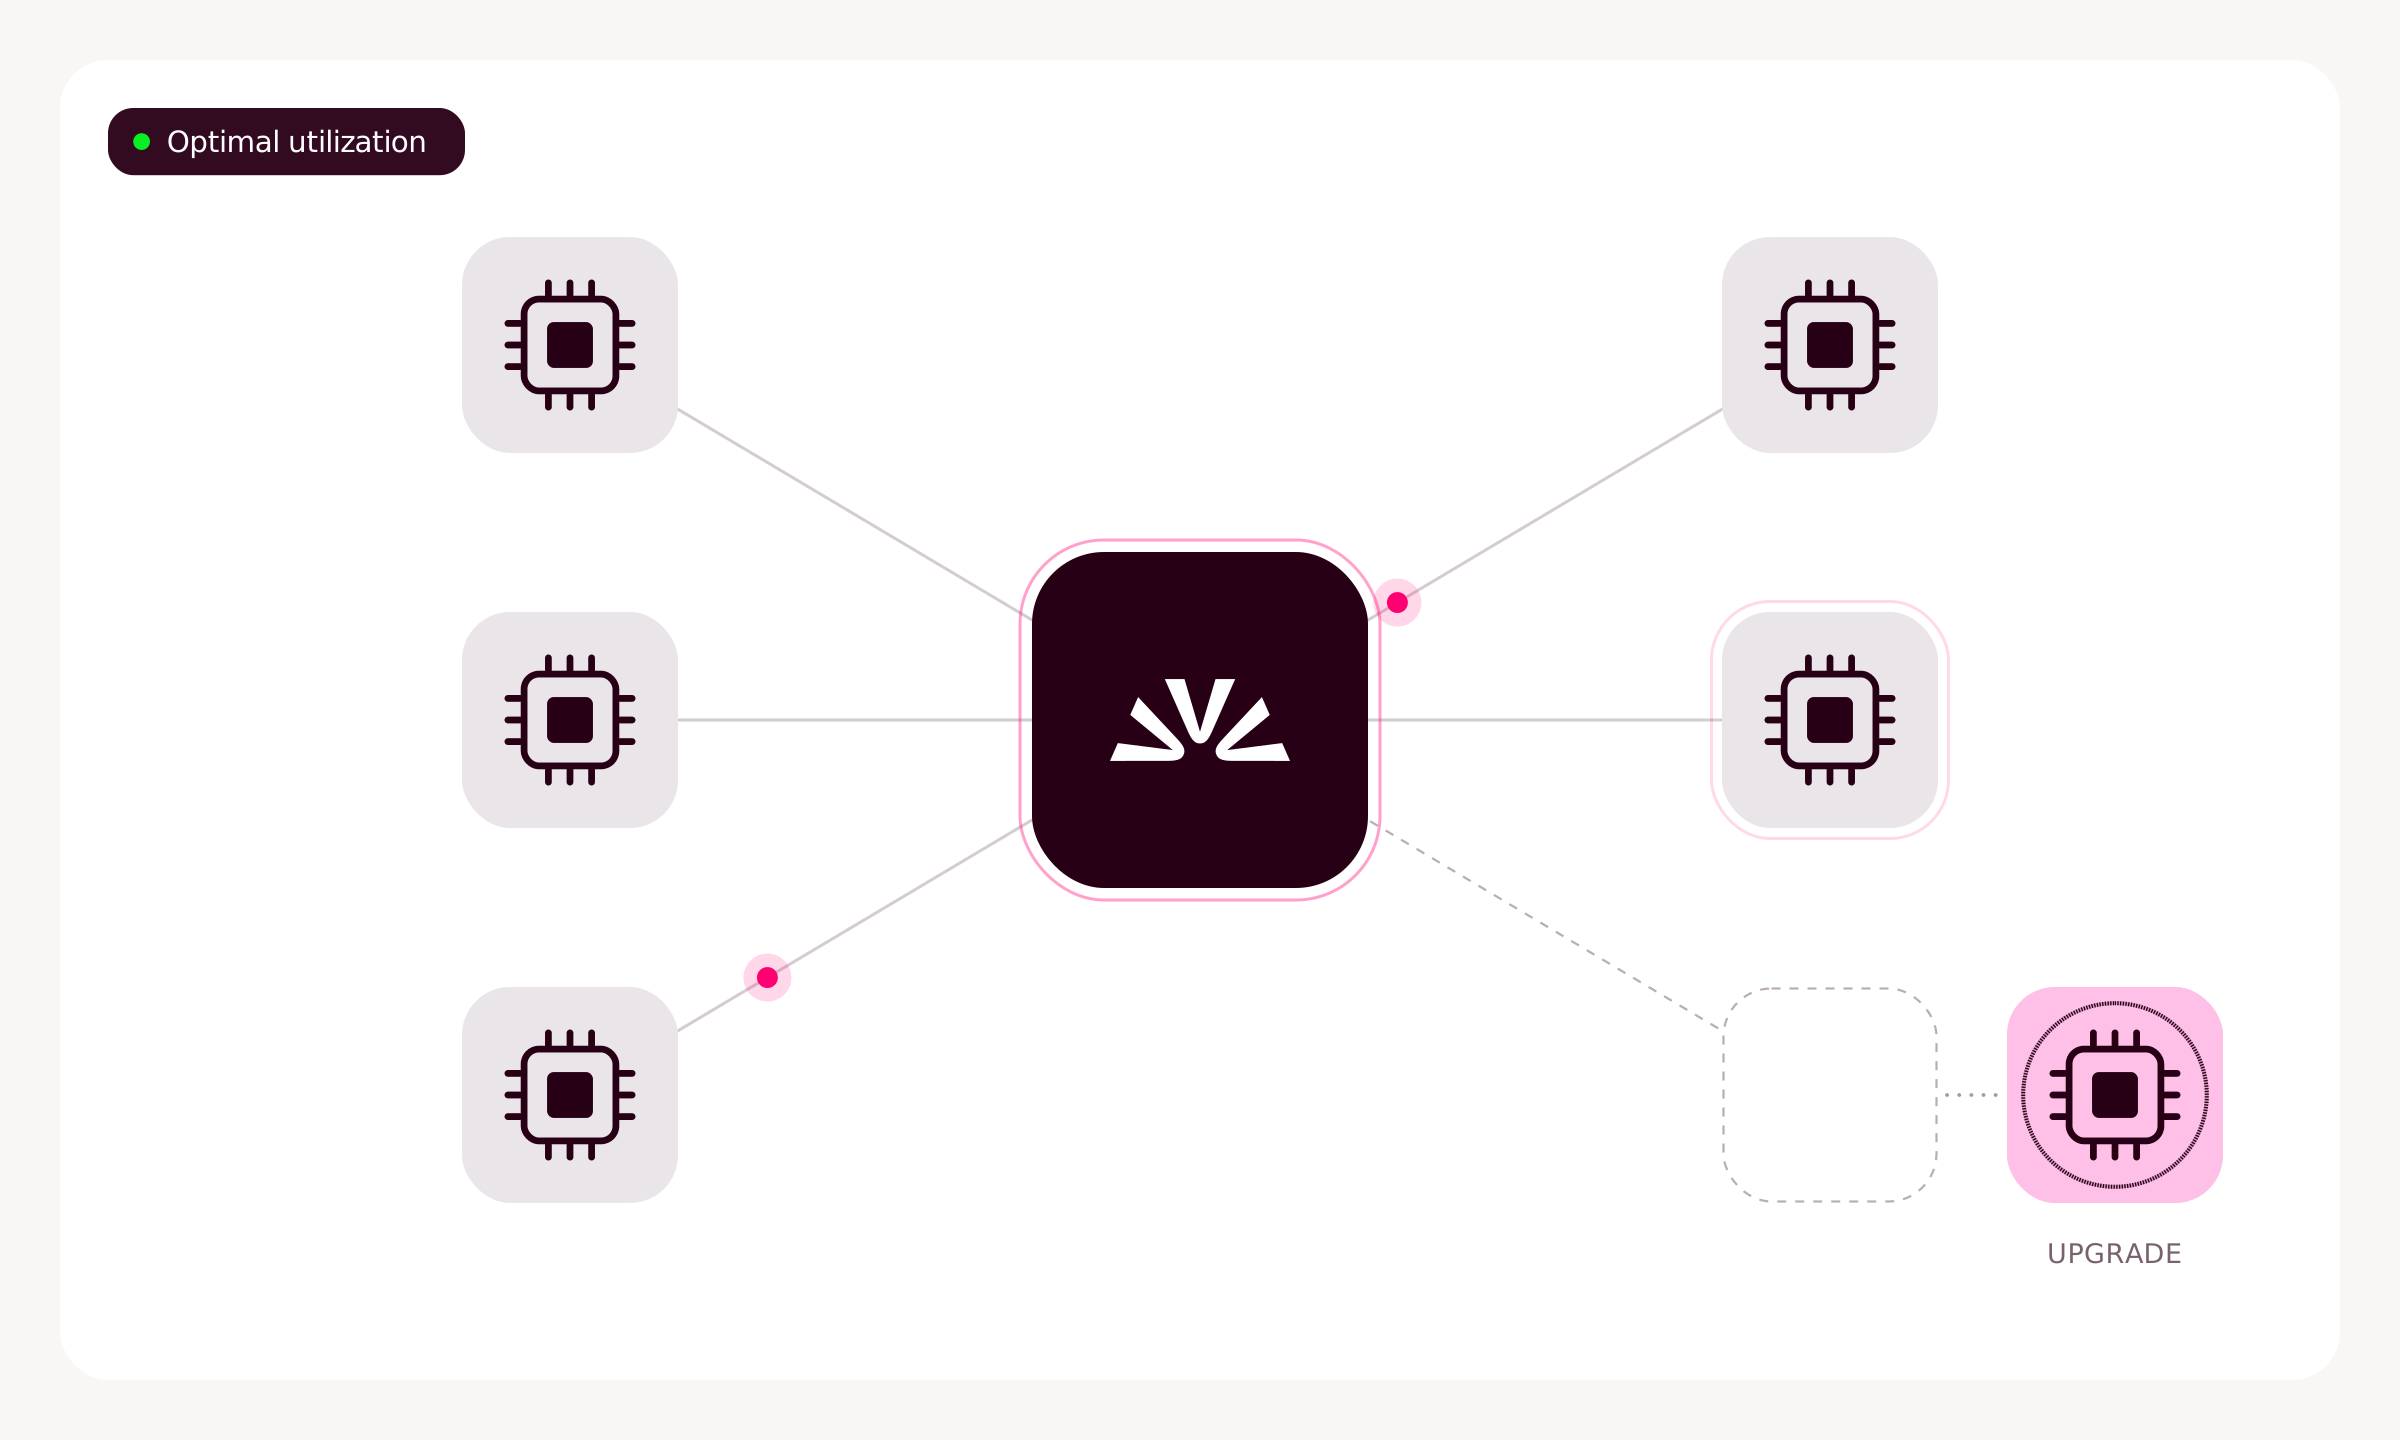
Built in-house, getting from GPUs delivered to tokens produced typically takes 6 to 14 weeks of driver, CUDA, NCCL, and RDMA work, then per-model tuning.
State-of-the-art open models typically run in your cluster within 24 hours of public release. Tool-call and reasoning parsers are configured for you.
Fireworks detects GPU and node failures, then drains and replaces affected nodes under live traffic, using spare capacity you provide.
Driver, CUDA, NCCL, and serving-stack updates are validated, benchmarked, and rolled out in your change windows, with rollback.
with your network edge and auditable access control
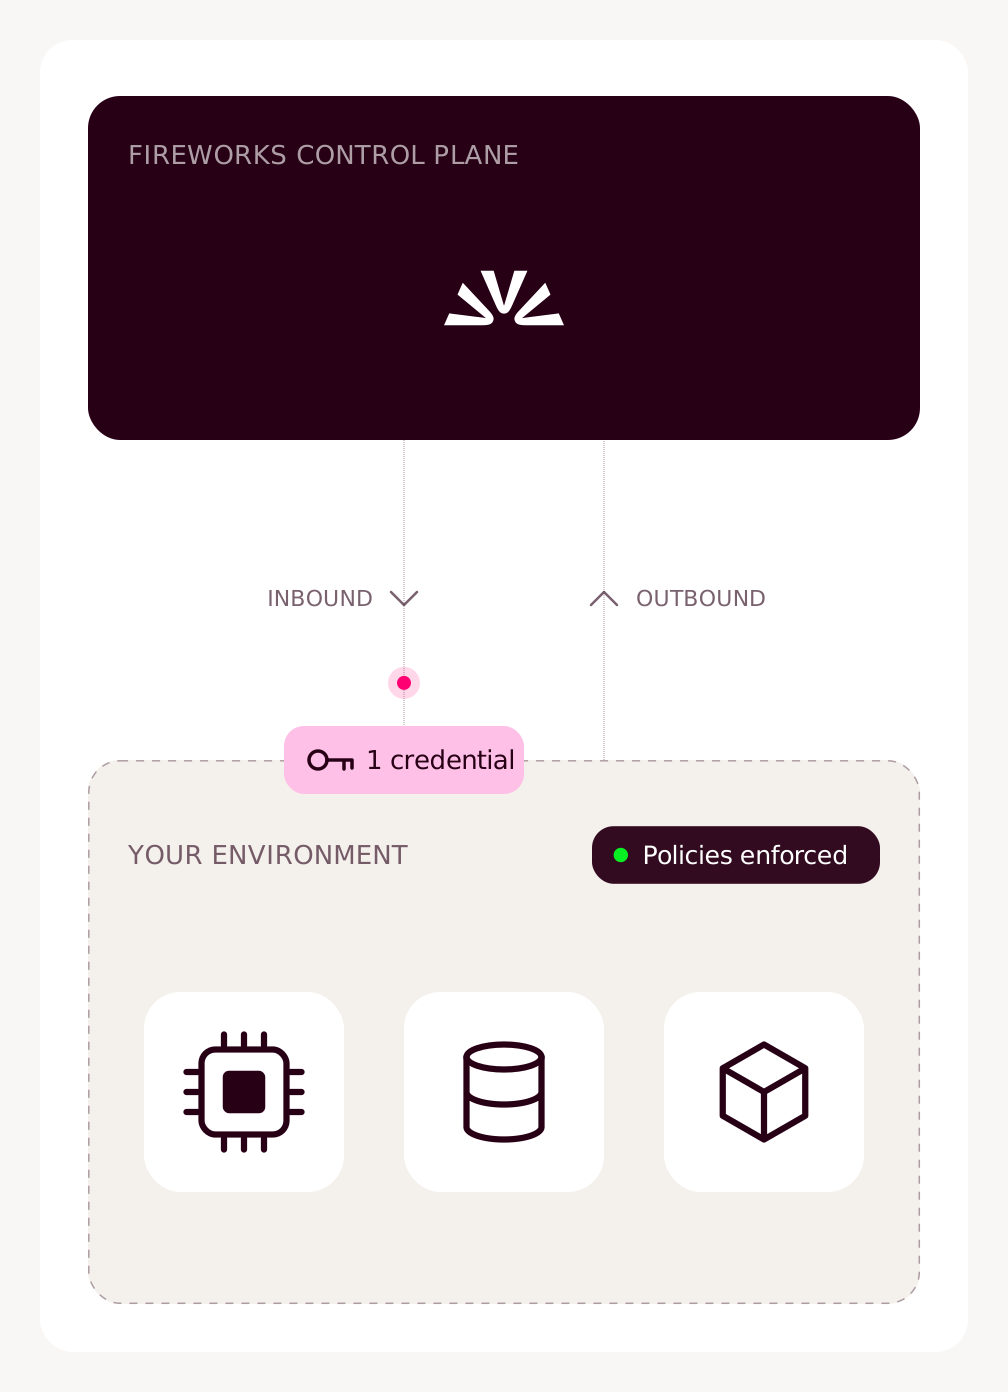
Inference runs on GPUs in your cloud or data center, under your network, access, and change-control policies.
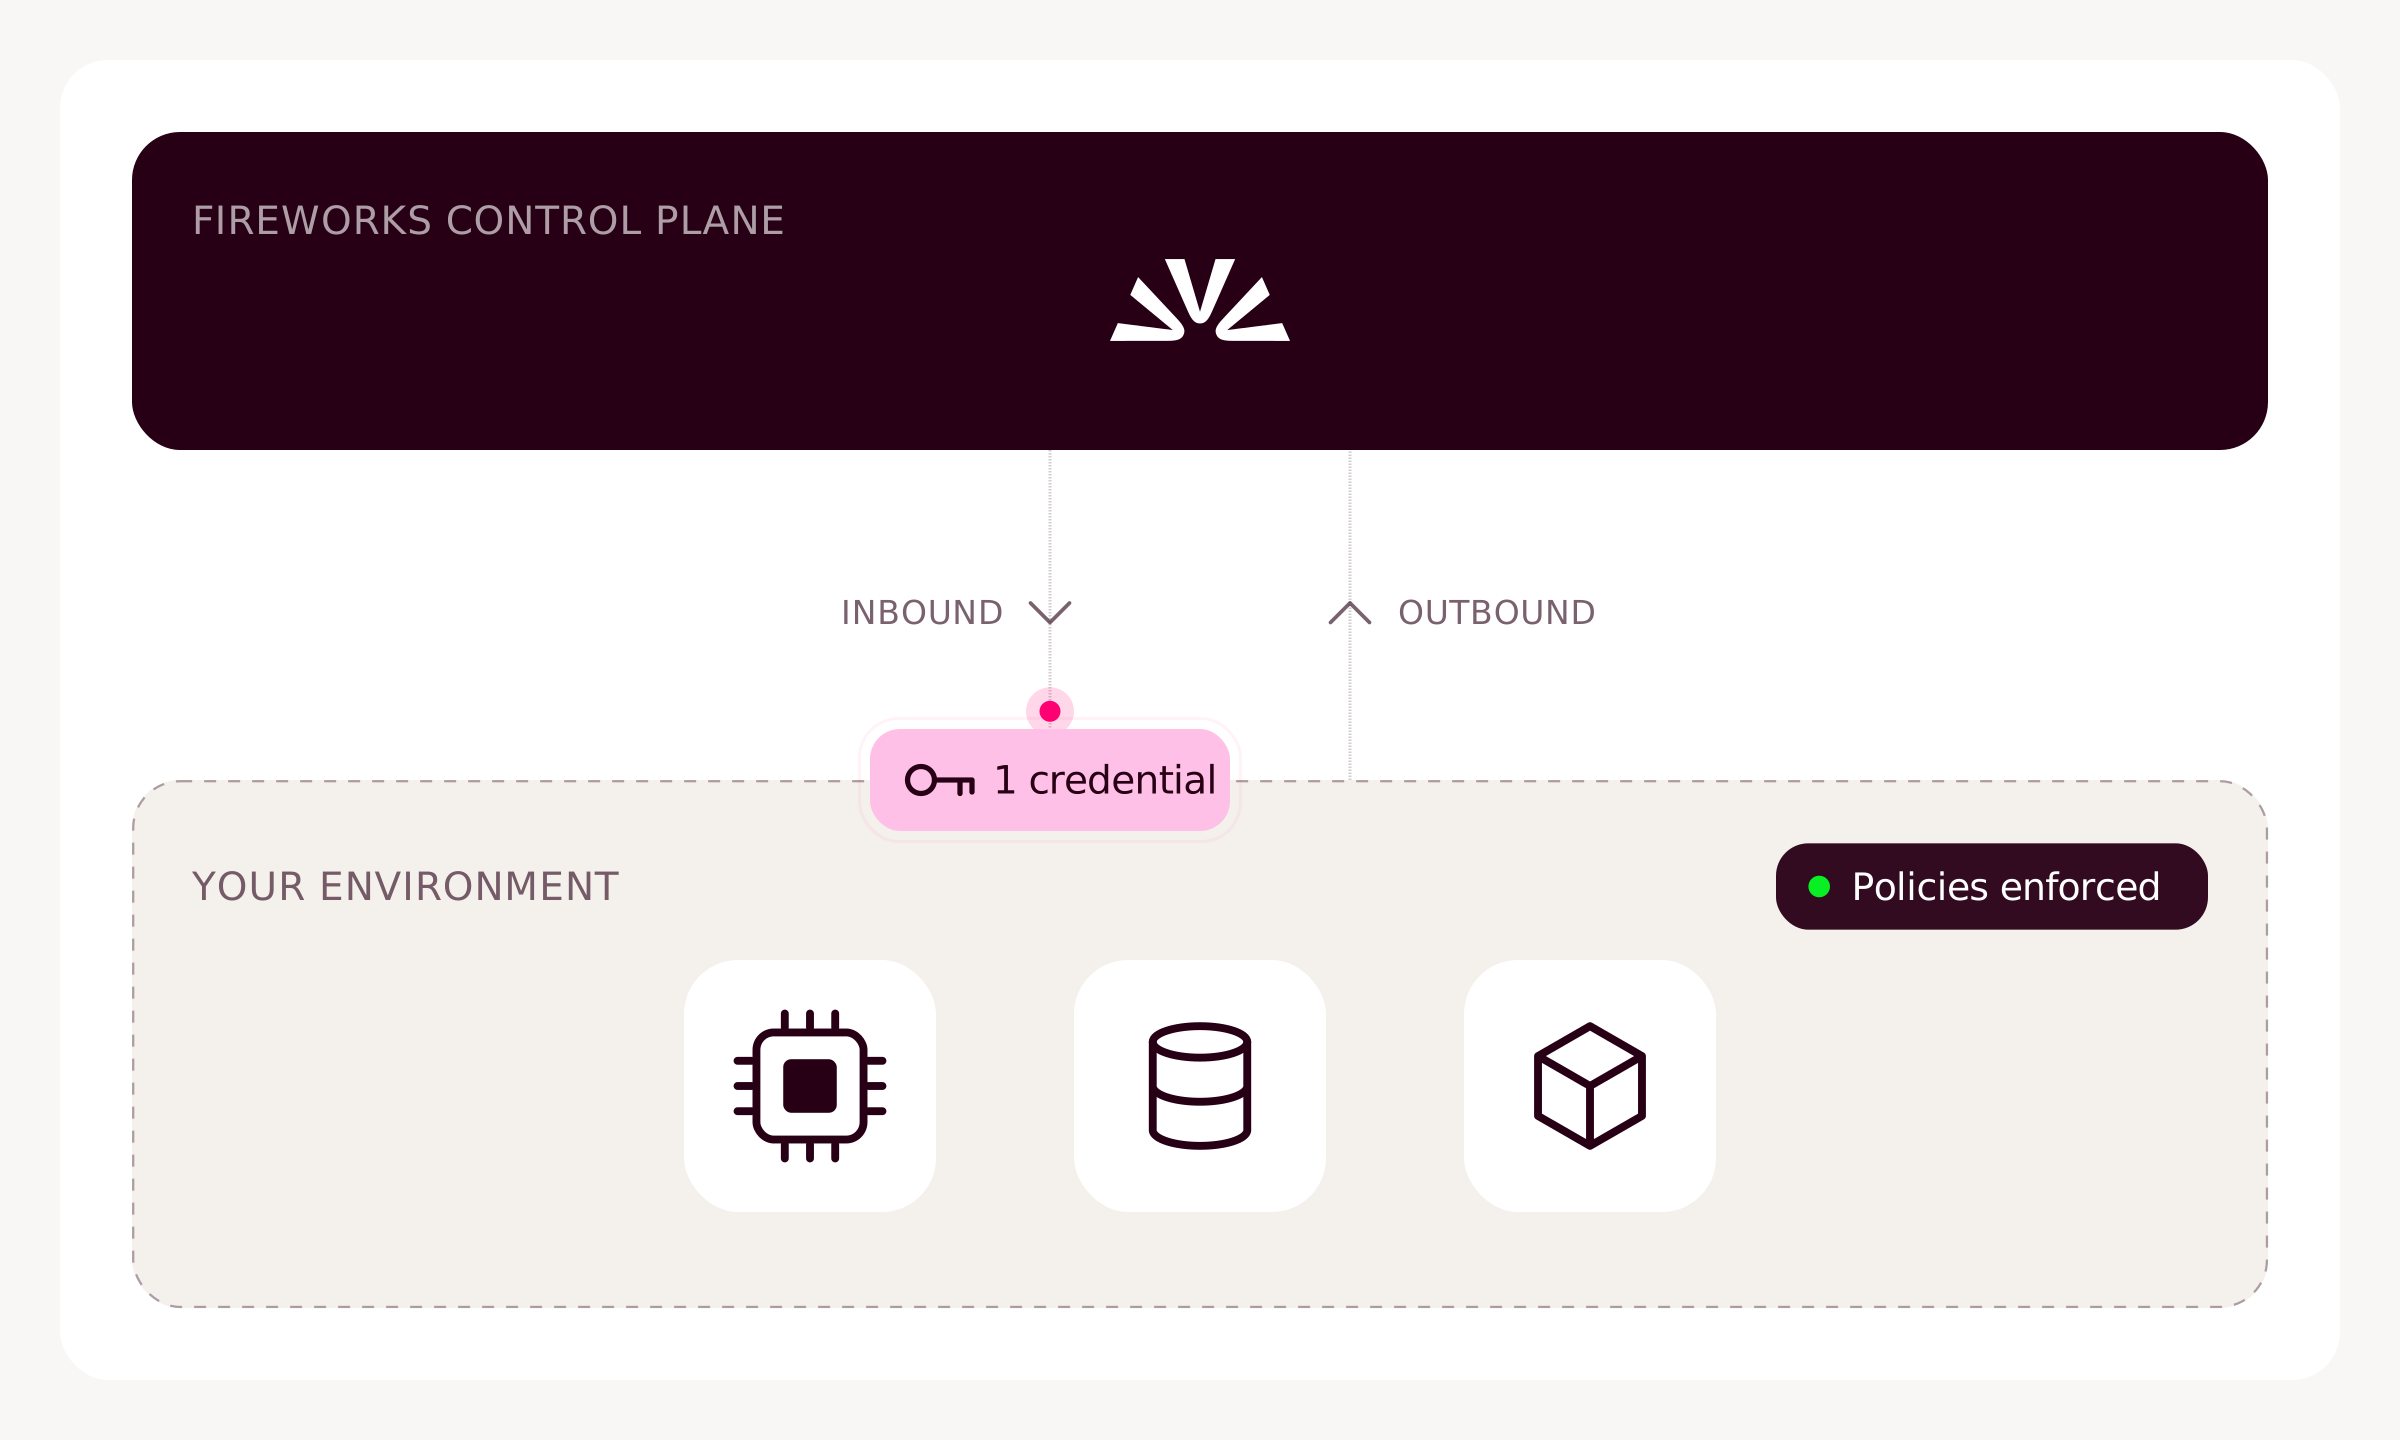
You manage ingress, the load balancer, DNS, and TLS certificates. The in-cluster gateway answers on your domain.
Inbound, the Fireworks control plane reaches your Kubernetes API over a dedicated credential. Outbound, only weight and image pulls plus operational telemetry.
Outbound traffic runs through your proxy, firewall, and registry allowlists.
Setup uses a dedicated, clearly named credential your team can audit and manage through your normal governance process. Components then run under scoped service identities.
with our proprietary inference engine: $14.5M a year of extra capacity per 1,000 B300s.
With Sovereign, every gain in throughput and utilization lowers what each token costs you.
FireAttention and FireOptimizer produce more tokens on identical hardware.
Self-managed fleets provision for peak and average 25 to 45% utilization. Batch, background, standard, priority, and low-latency modes share one cluster and fill the low-traffic hours, pushing sustained utilization toward 60 to 80%.
Throughput gain times utilization gain, on GPUs you already own.
Matching this in-house takes frontier kernel and serving engineers plus a GPU on-call rotation, roughly $4 to 6M a year before recruiting time.
When your cluster saturates, eligible workloads overflow to Fireworks Cloud in the regions you approve, then scale back to your GPUs as demand falls. Same API. No cold starts.
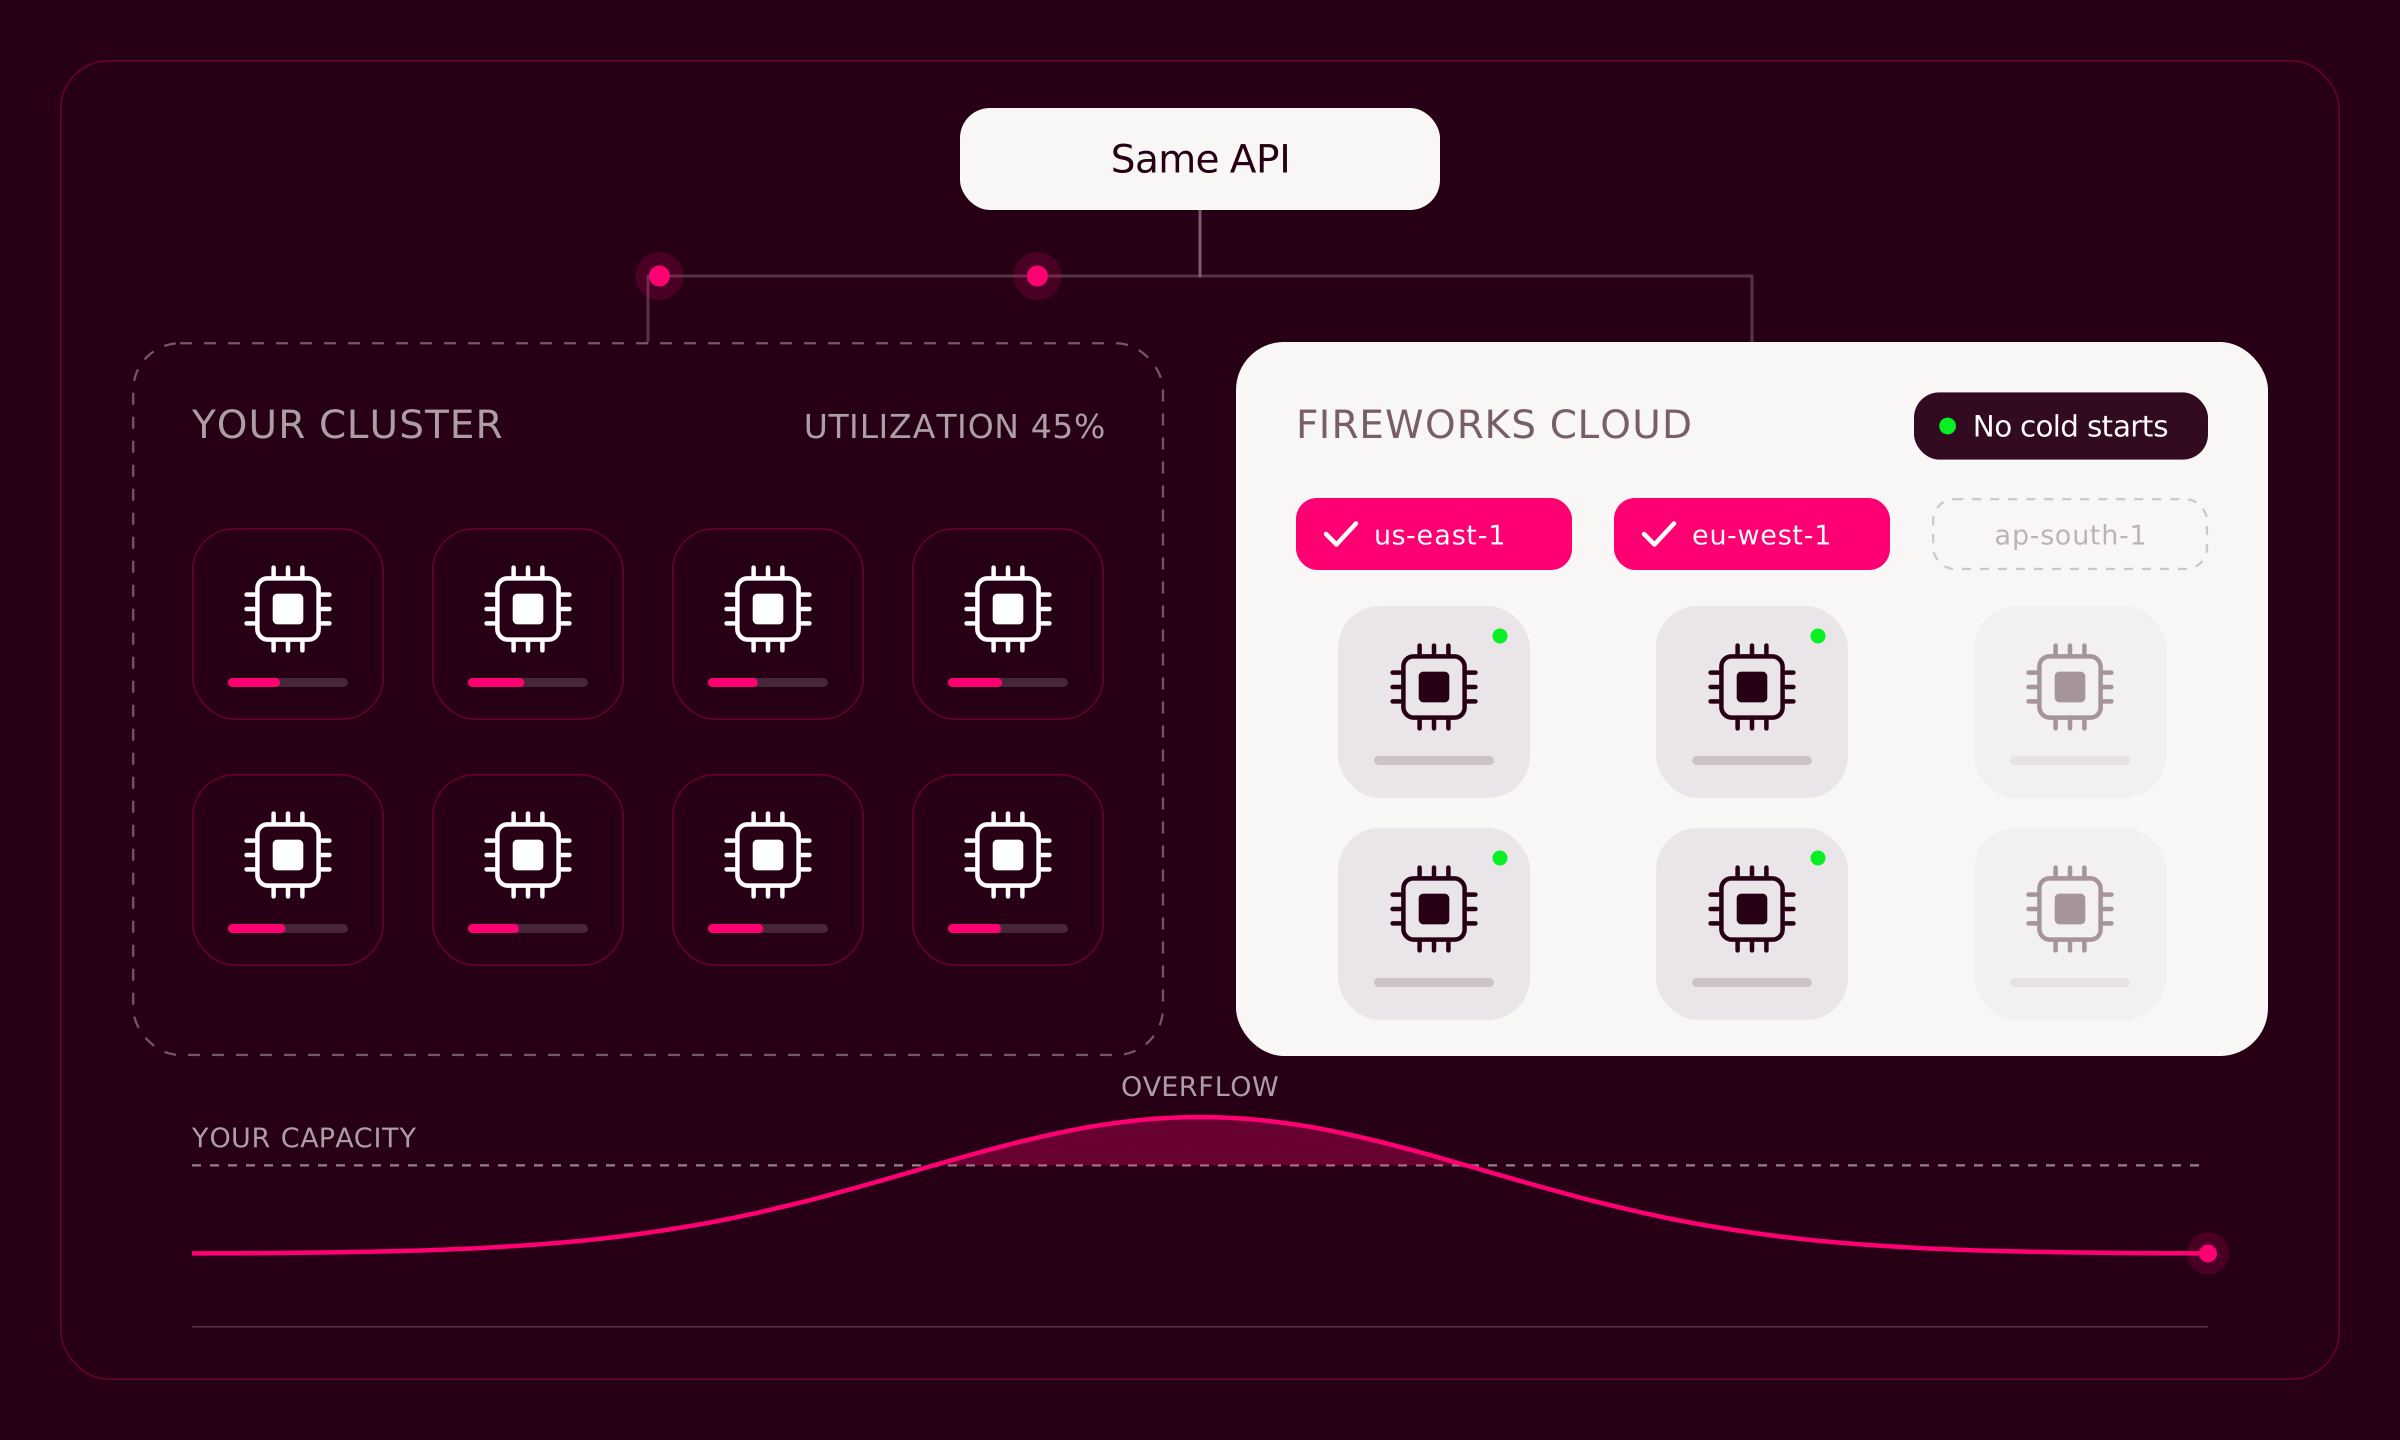
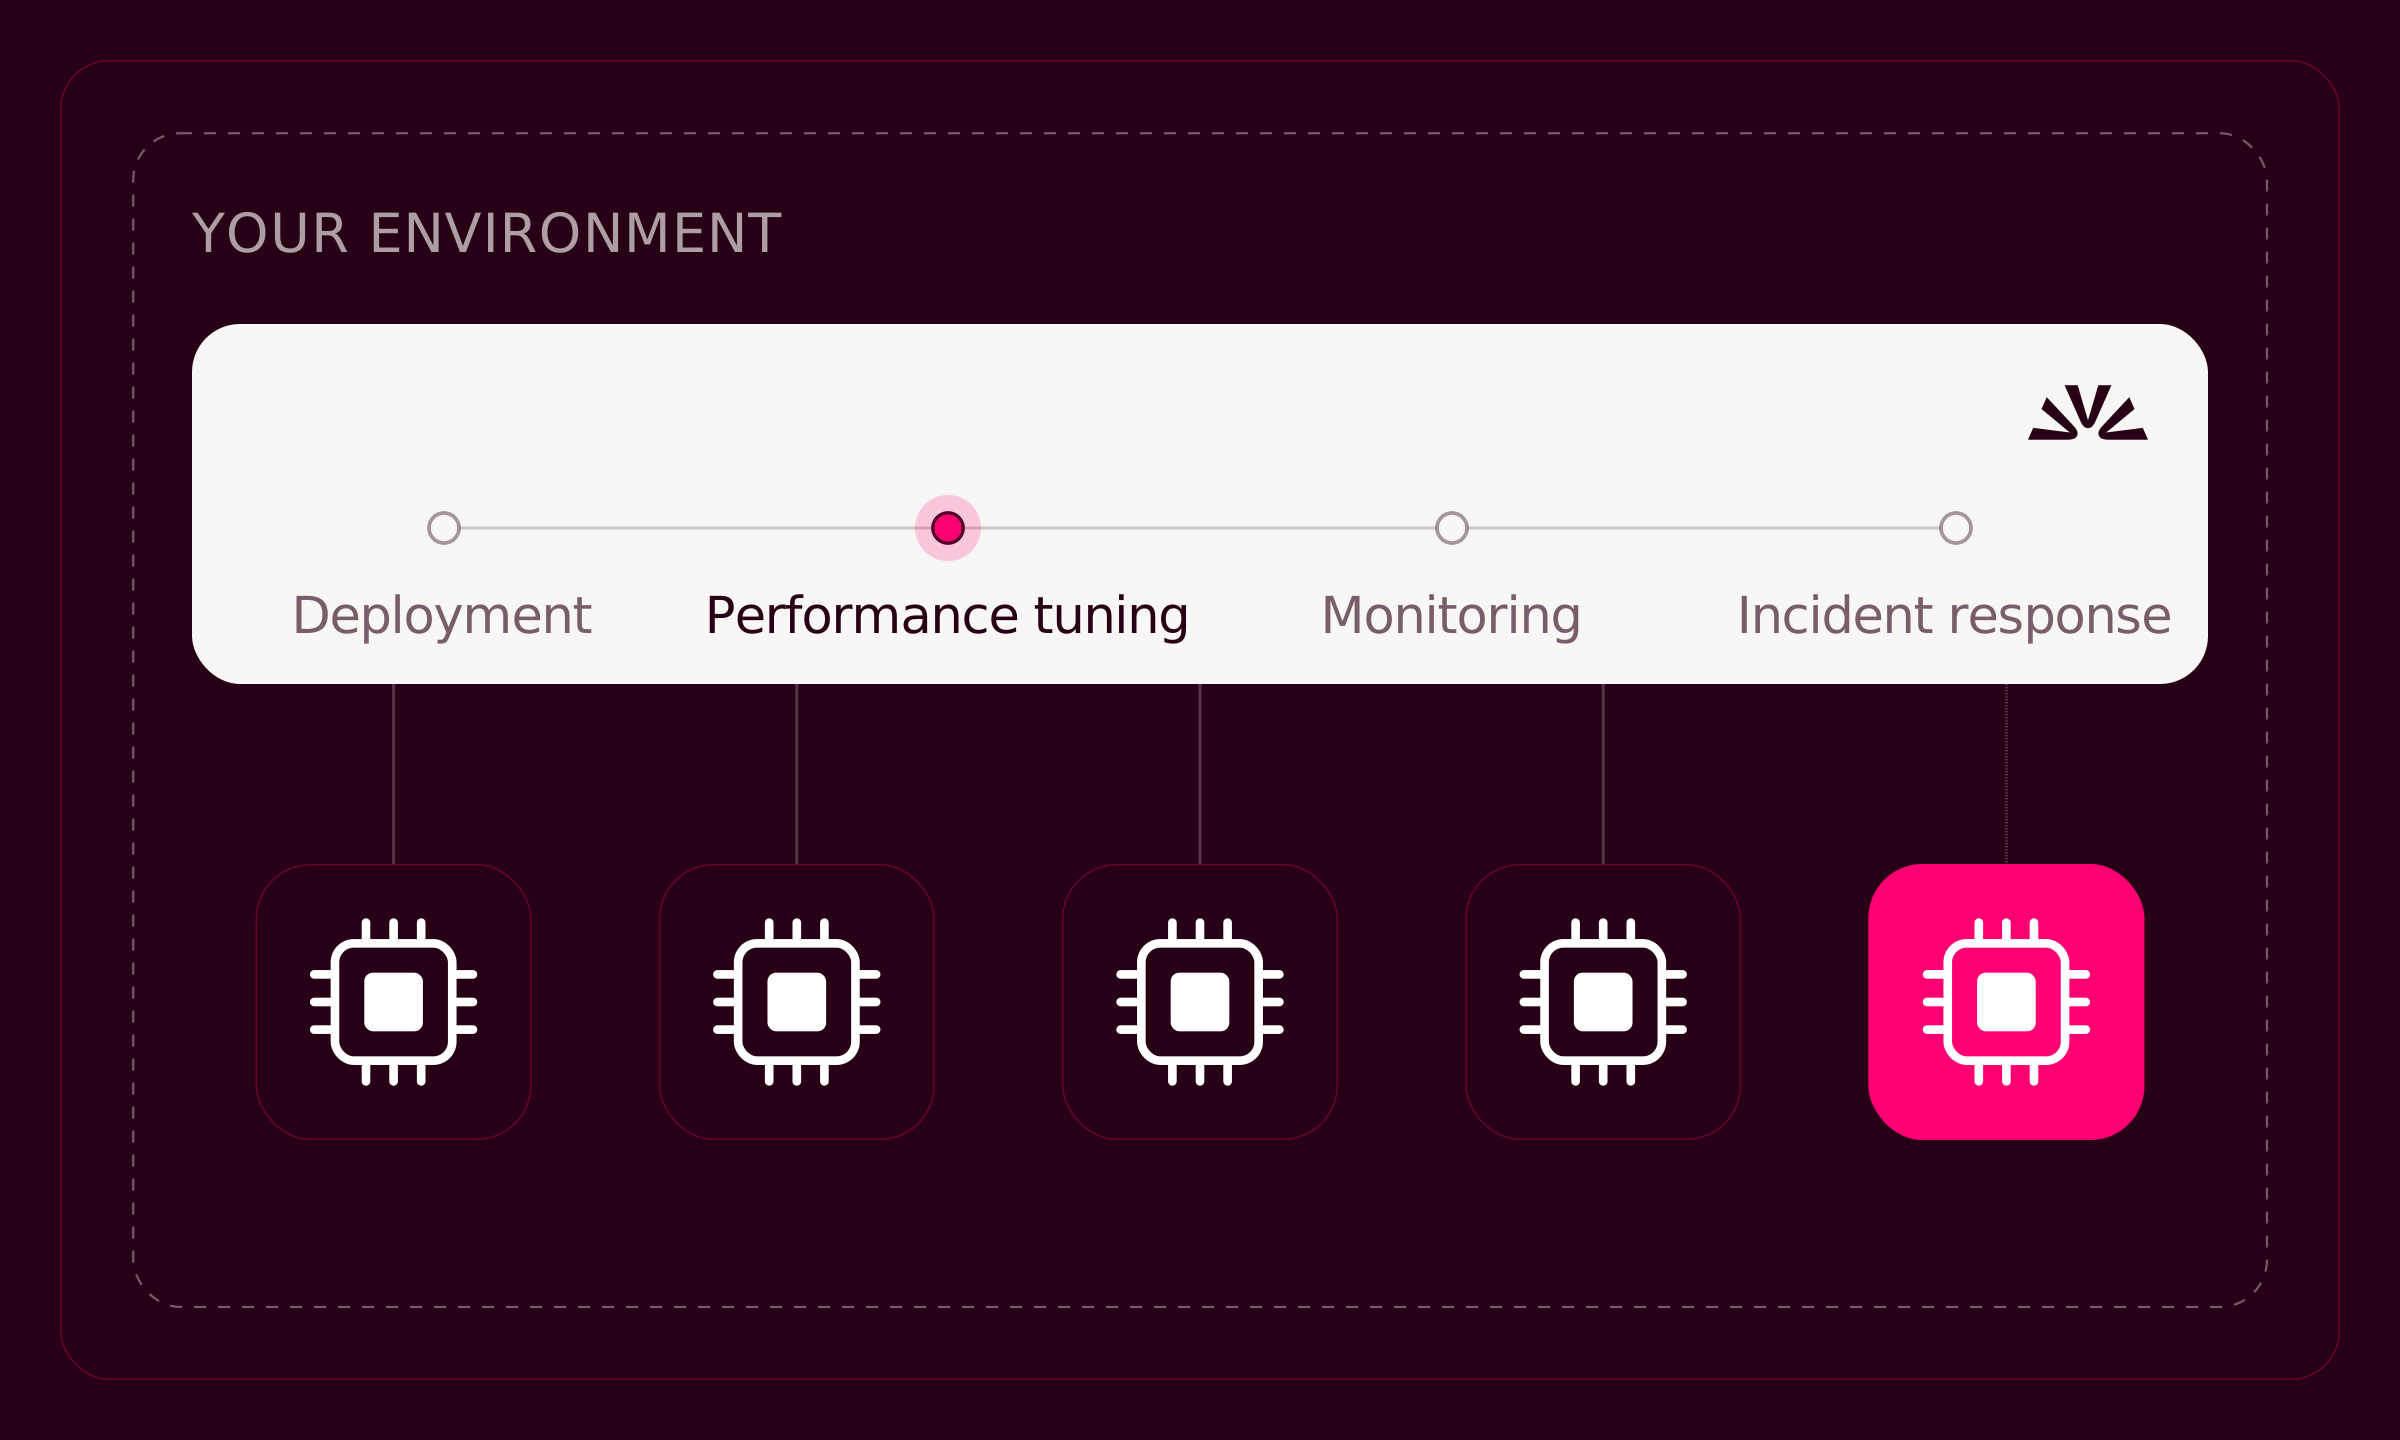
You own the environment and decide how it changes. Fireworks is responsible for serving models on it, from deployment and performance tuning to monitoring and incident response.
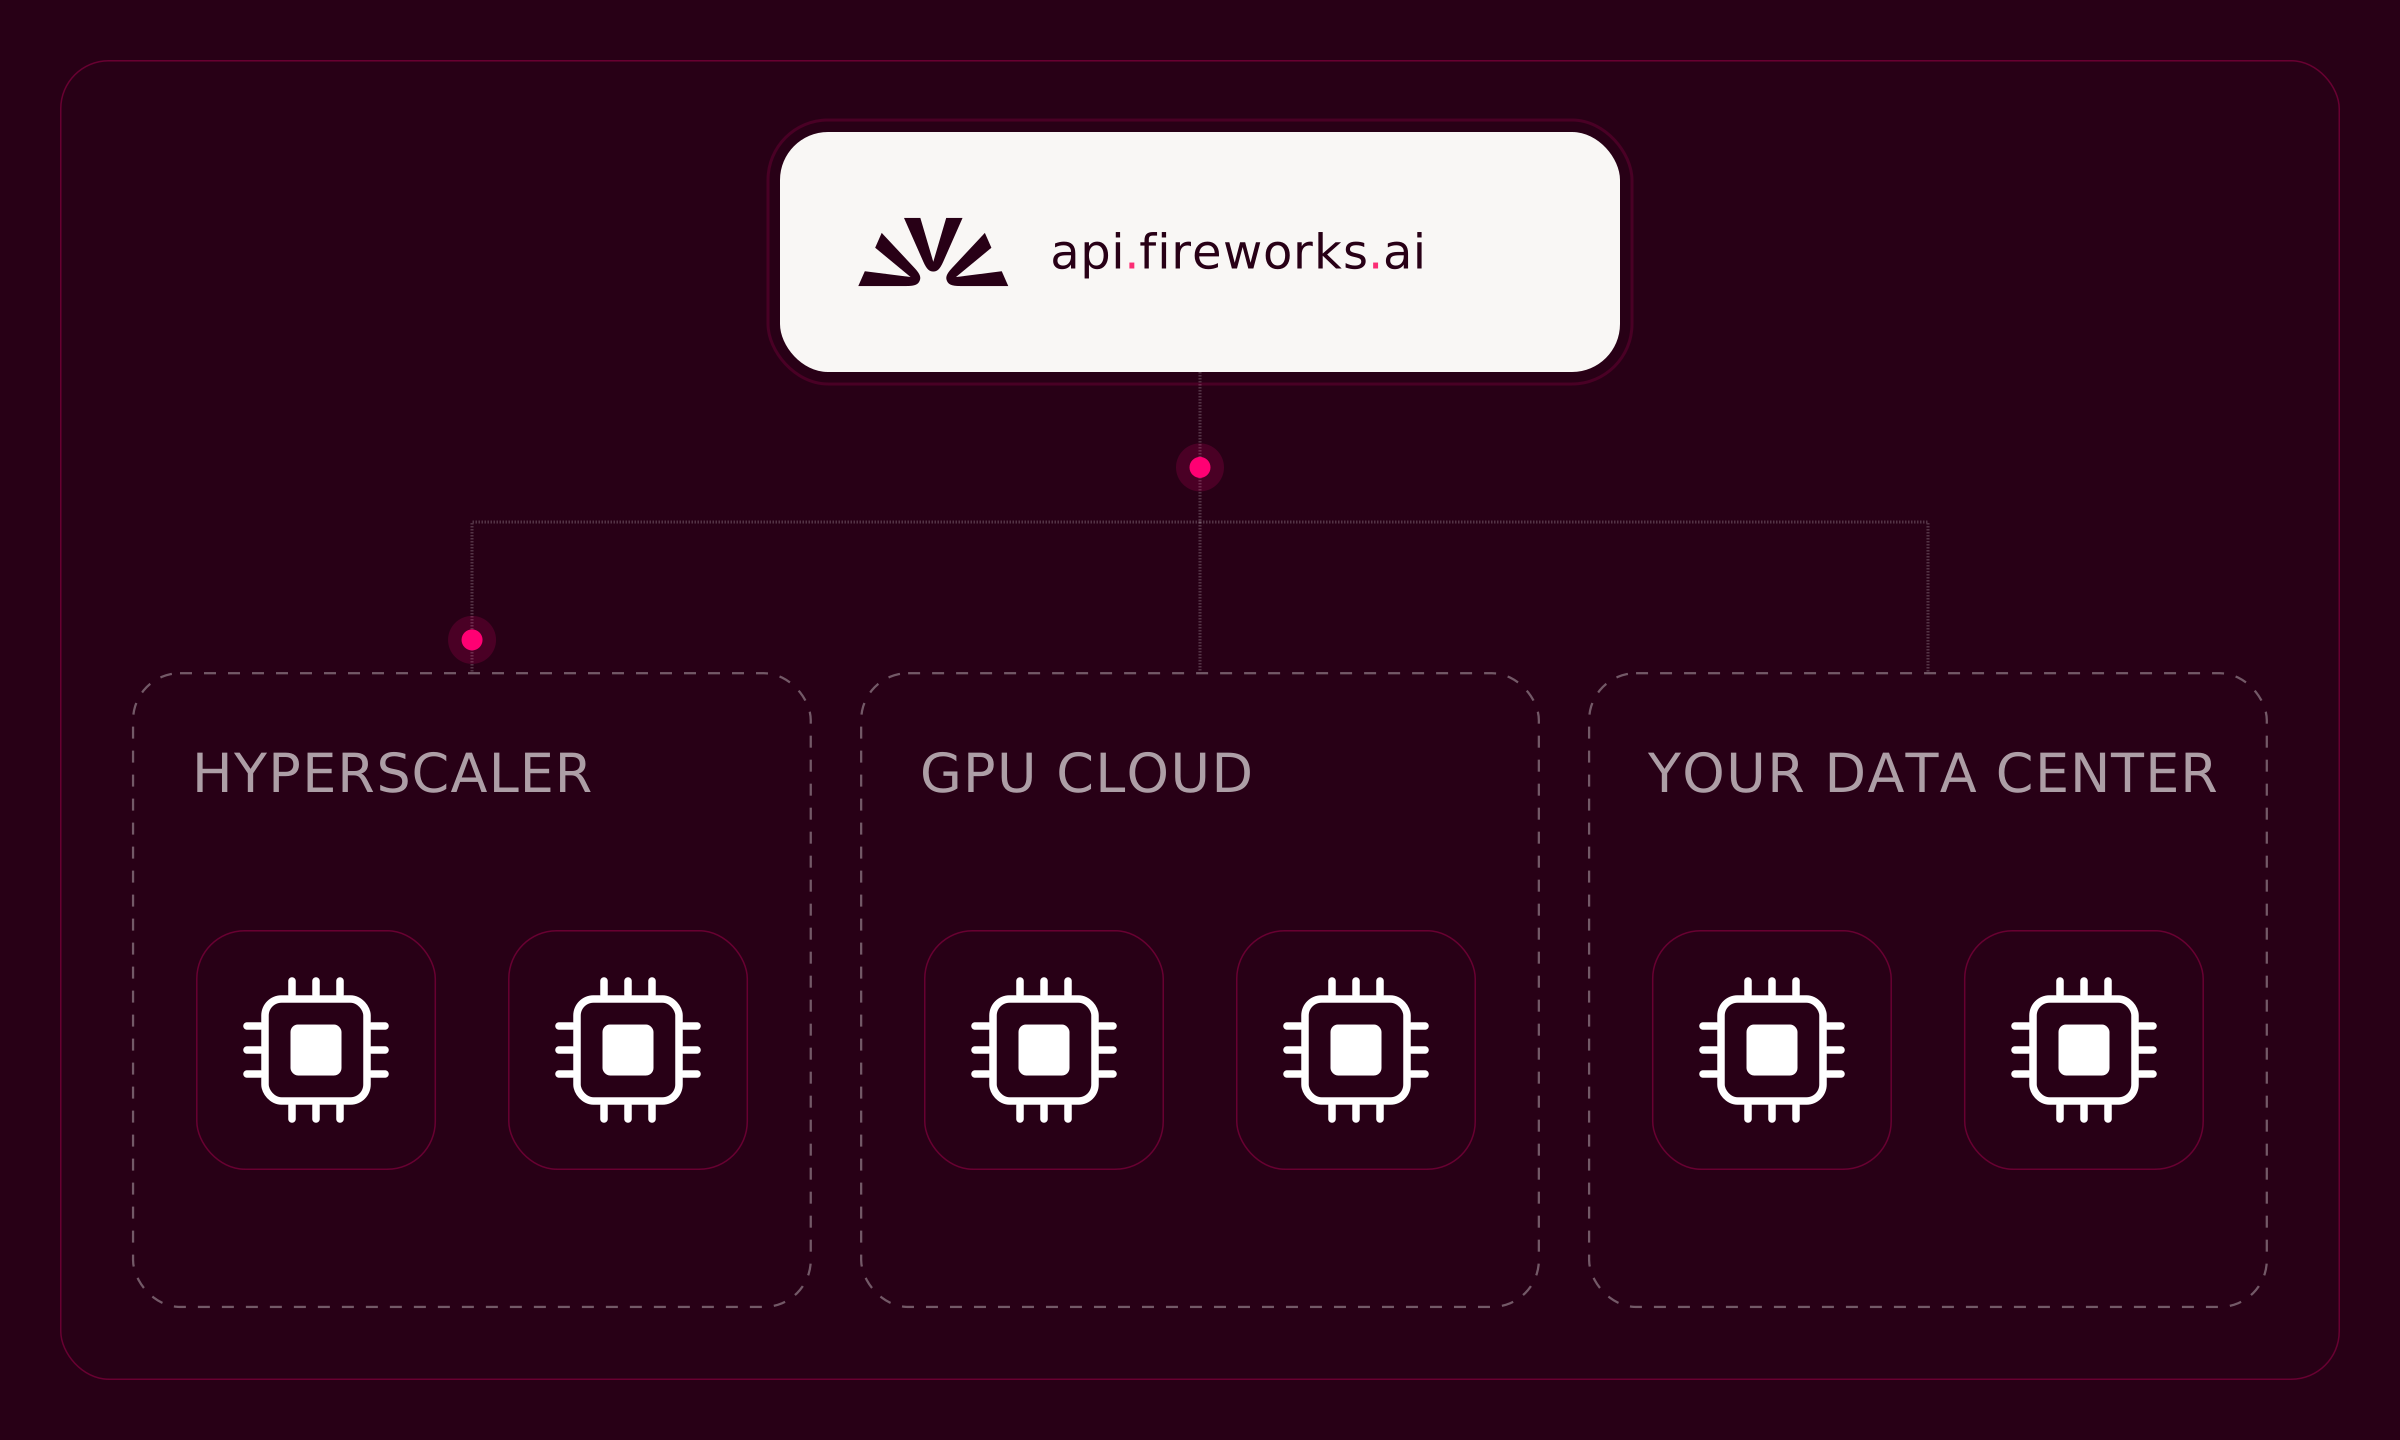
Run Sovereign in your hyperscaler account, on GPU cloud capacity, or in your own data center, across providers and regions, behind one Fireworks endpoint. GPU spend in your hyperscaler account still counts toward your cloud commitments.
Every connection to your cluster is documented, scoped, and auditable, and every change follows your approval process.
Setup uses a dedicated, clearly named credential your team can audit and manage through your normal governance process. Each component Fireworks operates runs under a scoped service identity.
You manage ingress, the load balancer, DNS, and TLS. Outbound traffic leaves only through the proxy, firewall, and registry allowlists you approve.
Fireworks makes model and deployment changes at your request and rolls out upgrades in agreed change windows, with monitoring and rollback. Escalation contacts are set before go-live.
SOC 2 Type II, ISO 27001, ISO 27701, and ISO 42001, with a HIPAA BAA and DPA available. Audit reports, the pentest summary, and certificates are in the Trust Center.
Sovereign runs the same inference engine, with the same model quality. What changes is who owns the capacity.
Feature
Benefit
Disaggregated prefill and decode, disaggregated KV caching, speculative decoding, and per-model quantization
More tokens from every GPU
FireOptimizer optimizes amongst 84,000 different serving configurations per workload
Tuned to your models and your traffic
NVIDIA driver, CUDA, NCCL, and kernel updates validated, benchmarked, pinned, and rolled out with rollback
New NVIDIA performance gains without rebuilding your inference infrastructure
Feature
Benefit
GPU and node failure detection, drain, and replacement under live traffic
Fireworks is responsible for detection and remediation
Managed rolling upgrades with canary and rollback
Every upgrade includes a tested rollback
Metrics, logs, dashboards, and incident response
Full operational visibility for your platform team
Quality checks on every quantization and decoding change
Model-quality regressions caught before release
Model and deployment changes made at your request
Model versions change only when you decide
Feature
Benefit
Same APIs and SDKs as Fireworks serverless and dedicated
Move workloads with no code changes
One global endpoint routes across your Sovereign clusters and optional overflow capacity
Run multiple clusters without building your own routing layer
Fine-tune on Fireworks serverless or dedicated, then serve behind the same API
Train and serve on one platform.
Start on pay-per-token, reserve throughput as you scale, or run Fireworks inside your own cloud. The same API works at every step.
Fireworks Sovereign runs Fireworks inference and training (coming soon) on Kubernetes clusters you own, in your cloud or data center. Fireworks operates the inference engine, and you retain ownership of the environment, cluster, GPUs, and networking. Sovereign is offered to Enterprise customers.
Requests enter through the Fireworks API gateway or private API gateway in your cluster, which authenticates and routes them. Inference and response handling run inside your cluster. Outbound traffic is limited to model weight and image pulls plus operational telemetry, through allowlists you approve.
For setup, you grant a dedicated, clearly named administrative credential that your team can audit and manage through your normal governance process. Each component Fireworks operates then runs under a scoped service identity. Teams with strict access policies can pre-create the required access structures.
Sovereign supports leading NVIDIA data center GPUs, including H100, B200, GB200, B300, and GB300 systems, in hyperscaler accounts, GPU clouds, or your own data center. Multi-node workloads require a qualified InfiniBand or RoCE fabric. Check our docs for the latest.
A production-grade Kubernetes cluster that Fireworks can reach, qualified NVIDIA GPU nodes, a compatible GPU software environment, model and cache storage, and customer-managed ingress, DNS, and TLS. Check our docs for the latest requirements.
Our team can build a workload-specific TCO estimate from your hardware cost and traffic profile.
Timelines depend on procurement, cluster build, and qualification. Once your cluster is qualified, models typically serve within days.
Eligible workloads can overflow to Fireworks Cloud in the regions you approve, on the same API, then return to your GPUs as demand falls. Eligibility and regions are set during onboarding.
Fireworks deploys, updates, and version-manages models in your cluster. Changes are made at your request and roll out in agreed change windows.
Sovereign fits best when you own or have contracted GPU capacity, run production-grade Kubernetes, and keep utilization high. It also fits when inference has to stay in your environment for residency, sovereignty, a regulated data class, egress restrictions, latency co-location, or committed spend you need to draw down. If you have no owned capacity, spiky traffic, need capacity in days, or require a hard air gap, start with Fireworks serverless or dedicated.
Start with an architecture and qualification workshop. Our engineers run your models against representative traffic on your target hardware, then size your deployment.