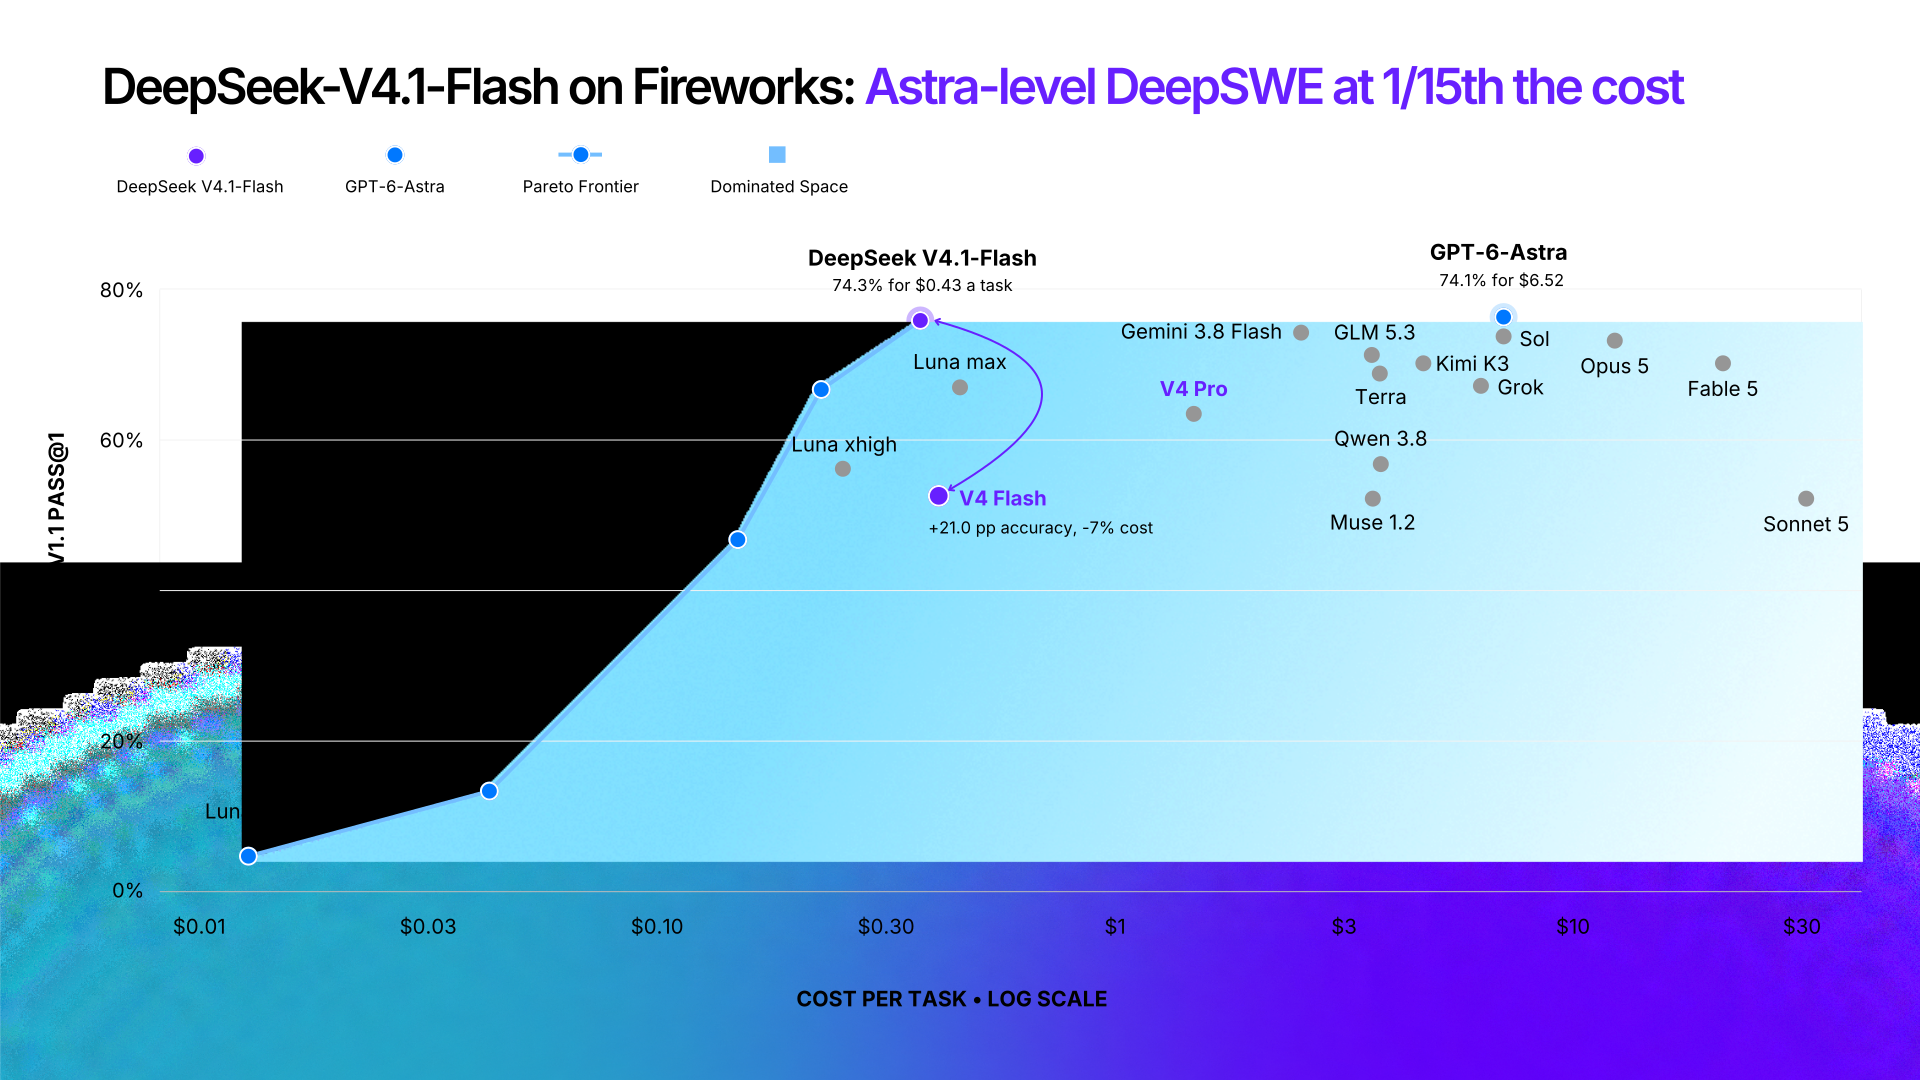
Last week, Fireworks released the latest DeepSeek-V4.1-Flash. After putting it through a full suite of benchmarks, the results show it sets a new pareto frontier across key tradeoffs like quality, speed, and cost. On DeepSWE, it hits GPT-6 Astra-level coding accuracy at 1/15th the price per task.
Developers often ask us how to pick the right model. The reality is that a model is just a single point on a map, but your application is a full system. AI capabilities are jagged, meaning a model that handles one task brilliantly might struggle with another. Because no single model wins across every scenario, workload design comes down to matching the right model to the right task, whether you need low-latency processing or deep computation for complex reasoning.

Here is how DeepSeek-V4.1-Flash actually performs across different workloads and where it could fit into your stack.
We evaluated the DeepSWE benchmark to see how models balance accuracy against cost per task.
| Model | Effort | Pass@1 | Cost/Task |
|---|---|---|---|
| DeepSeek V4.1-Flash | max | 74.34% | $0.430 |
| GPT-6-Astra | xhigh | 74.12% | $6.524 |
| Gemini 3.8 Flash | high | 73.83% | $2.362 |
| Claude Opus 5 | max | 73.65% | $11.838 |
On quality, these four models are the same class. On DeepSWE, all four land within 0.7 points on pass@1, and our run-to-run variation is 1.4 to 3.2 points, so no model in this group is far ahead of the others on quality. The differentiation comes entirely on cost: DeepSeek-V4.1-Flash on Fireworks delivers the same accuracy band at $0.43 per task, 5.5x below Gemini 3.8 Flash, 15x below GPT-6 Astra, and 28x below Claude Opus 5.
The new DeepSeek-V4.1-Flash model fundamentally changes the unit economics of autonomous software engineering tasks. Running high-iteration agent workflows, multi-turn bug sweeps, or large-scale test generation on expensive closed models like GPT-6 Astra and Opus 5 rapidly drains engineering budgets. At $0.43 per task, frontier-grade SWE agents become viable as continuous, background infrastructure. With DeepSeek V4.1 Flash, you can now run 15 autonomous coding attempts for the price of a single Astra call.
DeepSeek-V4.1-Flash is the smallest model in DeepSeek's new architecture family, and comes with some new architectural enhancements.
It is composed of 552B-parameter MoE with a new encoder–decoder split architecture. In this architecture, instead of one activation budget for an entire forward pass, the model splits it into 8B active parameters for input, and 16B for output. This results in a more efficient design, resulting in more economical token spend.
That asymmetry aligns with how coding agents operate. A typical agent trajectory is very input-heavy. A coding agent often re-reads files, re-reads its own scratchpad, re-reads tool output, and emits a comparatively small patch. In our DeepSWE run, the model consumed 36.9M input tokens per task against 211K output tokens, a 174:1 ratio. This architecture enables developers to spend half as much compute on the input side, which is typically where a larger percentage of tokens exist.
DeepSeek improved the KV Cache utilization on DeepSeek-V4.1-Flash compared to previous generation DeepSeek V4, only consuming ¼ the HBM, and ⅛ the SSD Storage.

This new KV Cache optimization unlocks better economics for your coding agents. From the DeepSWE run, we had the following economics:
| Cost Component | Tokens/Task | Rate | Cost/task | Share |
|---|---|---|---|---|
| Uncached input | 148,741 | $0.22/M | $0.0327 | 7.6% |
| Cached input | 36,744,586 | $0.007/M | $0.2572 | 59.9% |
| Output | 211,513 | $0.66/M | $0.1396 | 32.5% |
| Total | $0.4295 |
99.6% of input tokens on this run were cache hits, and cache-hit charges are 60% of the bill.
Most people assume your agent economics results in you mostly paying for what the model generates. However in a long-running agent loop, the majority of the spend comes from re-reading the same context repeatedly. This spending loop from repeat tasks, makes a 4x reduction in KV cache memory have a greater impact on your token spend. It directly targets the biggest cost driver in your agent design, bringing a 74%-class DeepSWE score down by 15X. The 8x reduction in SSD overhead plays a complementary role to the HBM optimization, by keeping cache hit rates near 99% across long trajectories.
On a different task, we see something similar DeepSeek-V4.1-Flash is approaching the frontier at a fraction of the cost.
| Model | Accuracy |
|---|---|
| GPT-6-Astra | 87.5% |
| DeepSeek-V4.1-Flash | 86.5% |
The results on Terminal-Bench 2.1 are one point a part on quality, but the economics is significantly different. DeepSeek-V4.1-Flash uses roughly 4x more output tokens on average than Astra, meaning it thinks longer and writes more.The results is 20x most cost optimized on output pricing alone. When you combine everything, including uncached input, cache hits, and output, DeepSeek-v4.1-Flash results in 12x lower cost per task at almost the same quality.
We ran a third benchmark task, Humanity’s Last Exam, also known as HLE. This is a multi-modal benchmark to measure the limits of the LLMs across graduate-level academic subjects. In this testing, we also performed some benchmarking with oracle routers, similar to what we have done with Kimi K3 and DeepSeek V4 Pro. As a quick refresher: oracle routing is a method for measuring the best theoretical performance by running the task through each model and then picking the cost-optimized correct option to establish the cost and performance ceiling.
| Configuration | HLE Score |
|---|---|
| DeepSeek-V4.1-Flash | 34.52% |
| GPT-6-Astra | 50.40% |
| Oracle Router (Best-Of GPT-6-Astra + DeepSeek-V4.1-Flash) | 54.80% |
On HLE, DeepSeek-V4.1-Flash trails Astra when run alone. This shows that DeepSeek alone is better suited for agentic coding tasks like DeepSWE, than reasoning tasks like HLE. If your workload is only hard scientific reasoning, this may not be the right choice.
The oracle router was the interesting result here, that shows the importance of routing, and multi-model systems. The oracle router for Astra plus DeepSeek V4.1 performed better than GPT-6 Astra alone. This 4.4% difference is only achievable if V4.1-Flash correctly answers a meaningful set of questions Astra gets wrong. The 34.52% is not a subset of the 50.40%; the two models fail on different problems. Something to consider is the oracle router is an upper bound possible for your application. A real router may not be able to capture the full 4.4 percentage point difference, but the oracle router shows the possibility for a system of models to achieve better than a stand-alone Astra model.
Fireworks’ DeepSeek-V4.1-Flash sets a new cost-performance baseline by matching top models like GPT-6 Astra on coding accuracy at 1/15th the cost per task. Its 552B MoE design uses split input/output activation budgets alongside upgraded KV caching that cuts HBM usage, resulting in better economics for your coding agents. It falls behind on complex academic reasoning (34.52% on HLE versus Astra’s 50.40%), but because it solves different problems than Astra, pairing the two in a routed system beats Astra alone at a fraction of the budget.
Here is how you can start building today:
Trying it out on your workloads? We'd love to hear about your experience, so tag us on X (@FireworksAI_HQ) and let us know what you're building!
