NewJoin us for our inaugural conference, Forge 2026

Disaggregated Inference Engine

The fastest and most efficient platform to serve open models.

Fast Inference

Purpose-built inference stack from hardware to runtime

Fireworks delivers unmatched speed and cost efficiency with a fully disaggregated engine. We optimize every layer—from quantization and caching to GPU memory layout—so you get peak performance, instantly.

Serving engine custom-built for performance
Model Access

Serve optimized models on day one

Fireworks delivers new models with day-zero support and model-specific optimizations, so you get fast serving immediately instead of waiting months. Fireworks is an official model launch partner for model providers like Meta and Mistral, so you never have to wait for models.

Unlock optimal efficiency by personalizing for your workload
Efficiency

Optimizations for long, multi-turn workloads

Get the best results on long prompts and sessions using our custom architecture. We apply multi-node expert parallelism, disaggregated KV caching, and prompt-aware request scheduling to drive performance even at scale.

Optimization

Multimedia Inference

The most performant stack to process and generate audio, images, PDFs and multimedia AI

Audio Transcription

Lightning-fast, low-cost audio transcription

Fireworks runs Whisper based transcription 4× cheaper and 10× faster than OpenAI. With built-in features like translation, alignment, voice activity detection, and preprocessing, you get full audio insights out of the box. Easily connect transcriptions to co-located LLMs to power real-time voice agents and voice understanding pipelines.

Serving engine custom-built for performance
Image Understanding

Customizable image and document understanding

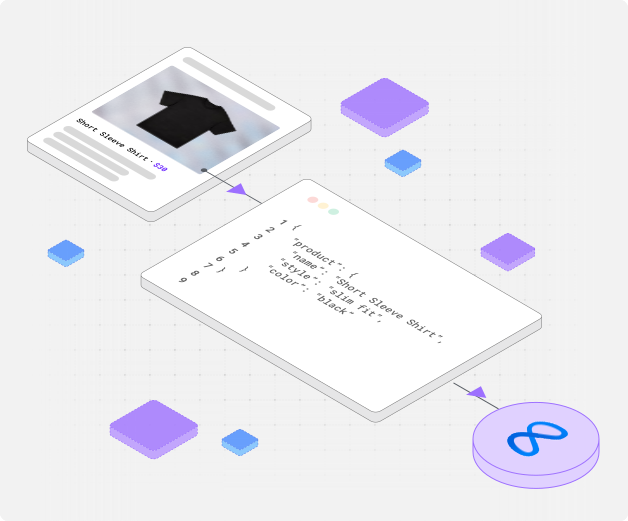
Serve open vision-language models with the lowest latency and highest flexibility. Extract, classify, and tag images and documents—then pass structured outputs to downstream LLMs with ease.

Serving engine custom-built for performance