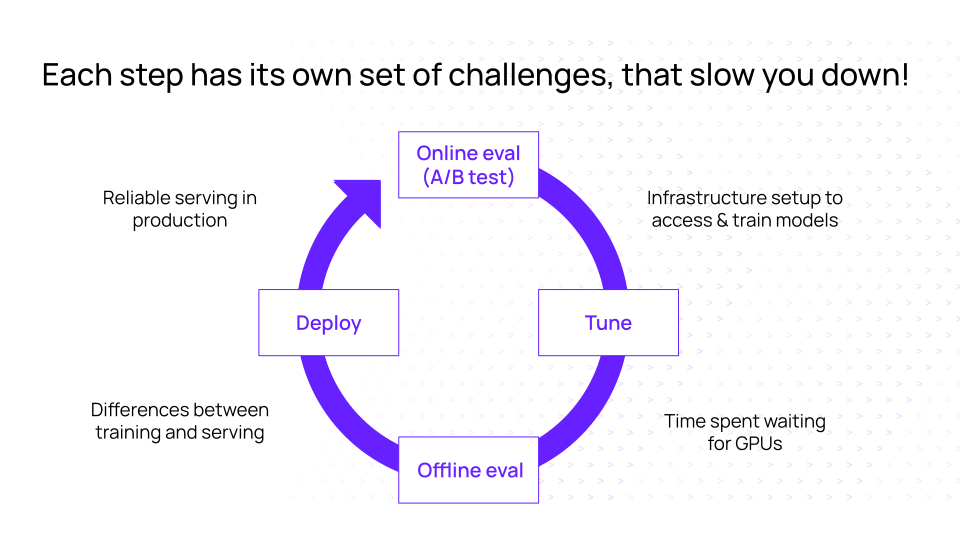
When building AI agents, the best AI companies are jointly developing their product and models in a process of rapid, continuous iteration. Just as we saw the rise of CI/CD pipelines in software, we now see a similar pattern emerging for building AI systems. This development lifecycle has four essential steps:
- Launch early, often testing multiple models, to get user feedback and collect interaction data from product usage
- Tune multiple candidate models using powerful post-training techniques
- Conduct offline evaluations to validate quality improvement and deploy the best performing models
- Deploy best performing models, and run online A/B tests to validate that your product metrics improve
Each step, however, has its own challenges that slow you down. Complex infrastructure setup and failures, time spent waiting for GPUs, reconciling differences between training and serving (both in data and use cases), and maintaining service reliability in production are all pain points that affect the iteration velocity of AI teams.
Fireworks Experimentation Platform: Reduce time to iteration from weeks to hours
To help address these challenges, we’re excited to announce the GA of the Fireworks Experimentation Platform – designed to supercharge your experimentation velocity by reducing your iteration time from weeks to hours. The experimentation platform offers powerful capabilities that help you move at the fastest possible speed:
✅ Build SDK with 1000s of models supported
Start building in seconds, without setting up infrastructure or wrangling multiple libraries - explore our model library.
🔧 LoRA Add-Ons: Run 100s of fine-tuning experiments in parallel
Make sure you’re not spending your time waiting for GPUs! LoRA Add-Ons allow you to run 100s of experiments in parallel. Instead of conducting experiments sequentially due to limited GPU capacity, you can deploy fine-tuned models as LoRA add-ons onto a single base model deployment.
This lets you scale your experimentation, with just a few lines of code in the Build SDK, without needing to run a huge GPU cluster or wait for capacity or cold starts.
🚀 Flexible Capacity: available on-demand, fully secure
Fireworks On-Demand offers flexible, single tenant capacity across our global fleet. On-demand deployments autoscale with your traffic, making it ideal for A/B testing. And you can transition seamlessly from training to production serving on Fireworks.
The Fireworks Build SDK: Rapidly Prototype with Open Models
To access the full capabilities of the experimentation platform, we’re also excited to announce the beta of our brand-new Build SDK, a tool to make rapid prototyping and experimentation on Fireworks easier than ever before. You can use the Build SDK to programmatically run experiments and evals, managing your entire AI workflow and Fireworks infrastructure through simple Python code.
Our SDK provides a declarative, object-oriented interface that treats Fireworks resources (e.g. deployments, fine-tuning jobs, and datasets) as simple Python objects. We designed it with four principles in mind:
- Object-Oriented: Work with Fireworks primitives as intuitive Python objects
- Declarative: Describe your desired state and let the SDK handle the reconciliation logic for you.
- Smart Defaults: The SDK automatically makes the most logical and resource-efficient choices, such as reusing existing resources instead of creating duplicates
- Fully Customizable: You have full access to every configuration parameter for complete customization
Code Walkthrough
It takes just a few lines of code to get started working with open models
pythonCopy12345678910
Curious how easily you can experiment at scale with the Build SDK? Watch Dylan run 125 experiments in 3 minutes using just a single deployment!

Powerful features that unlock experimentation with open models
Declarative Deployments
You specify the model you want and the SDK can automatically choose the best strategy across on-demand and serverless options, spinning up resources for you as needed
pythonCopy12345678910111213
Effortless Fine-Tuning
Fine-tuning a model is now as simple as creating a dataset and calling one method:
pythonCopy123456789101112
Programmatic Experimentation
You can easily script experiments across multiple models and configurations. If possible, the SDK will re-use existing deployments or leverage Multi-LoRA to be resource-efficient.
pythonCopy123456789101112131415161718192021
Smart Resource Management
The SDK’s smart defaults intelligently reuses and optimizes deployments to let you confidently scale experimentation volume
- Resource Signatures: Each resource has a unique signature that prevents duplicate creation
- Automatic Reuse: Existing resources are reused across your team when appropriate
- Resource Optimization: Built-in scale-to-zero and intelligent deployment choices
Getting started
The Fireworks Build SDK is available now and getting started takes less than 5 minutes:
1. Install the SDK
bashCopy1
2. Set your API key
bashCopy1
3. Start building
pythonCopy1234
What’s next
The Build SDK represents our vision for the future of AI development — where infrastructure complexity disappears and developers can focus entirely on creating amazing AI experiences through code.
We’re continuing to expand the SDK with new capabilities:
- Advanced multi-modal model support
- Enhanced fine-tuning workflows
- Better function calling syntax
- Deeper Fireworks platform integrations
Whether you’re building a simple chatbot or running complex AI experiments, we want to hear about your experience and are actively seeking feedback from the developer community. Get started with the SDK by:
- 📖 Reading the complete documentation
- 🚀 Trying the interactive tutorial
- 📧 Sharing feedback on Discord

